Enter opens the highlighted result. Esc closes.

Google Gemini 4 Carbon

  • Google
  • Released November 10, 2026
  • No public weights listed
  • 1.05M context

As of November 14, 2026, Google Gemini 4 Carbon ranks #2 of 118 models overall with 88.3 ±3.2 on the LLMBenchmark Index. Gemini 4 Carbon ranks #2 of 122 in reasoning, its strongest category. Google Gemini 4 Carbon costs $2.00 per million input tokens and $10.00 per million output tokens. Gemini 4 Carbon was released on November 10, 2026.

Gemini 4 Carbon's output price ranks 276 of 343 priced models, counting from the cheapest.

  • Coding index 86.6 Verified, 4 benchmarks
  • Cost per solved task Not computable No published attempt cost
  • Output, per million tokens $10.00 276 of 343 from the cheapest Maker's API price
  • Input, per million tokens $2.00 Maker's API price
  • Context window 1.05M Tokens per request
New model

Gemini 4 Carbon launch tracker

Listed on OpenRouter November 10, 2026, 4 days before our data. Results so far on 73 of 222 public boards; this page updates every day as boards publish.

About and specs

Gemini 4 Carbon is a frontier Gemini 4 model from Google for coding, agentic and complex reasoning work. It takes text, image, audio, video and file input, supports long decode...

API model id google/gemini-4-carbon
  • Tool callingListed
  • Structured outputsListed
  • JSON modeListed
  • Reasoning modeListed
  • Web searchNot listed
Takes in
Audio, Files, Images, Text, Video
Gives back
Text
Context window
1.05M tokens
Max output
944K tokens
Knowledge cutoff
Not published
Cached input $/Mtok
$0.10
Cache write $/Mtok
$0.1875
Reasoning $/Mtok
$10.00
Web search, per request
$0.014
Tokenizer
Gemini
Requests moderated
No
Withdrawn on
No date announced
Parameters
Not published
Downloads, all time
No public weights
Training compute
No estimate published
Output speed
66 tokens/s, High effort
Speed on OpenRouter
32 tokens/s via Google AI Studio, 30-minute median
First token on OpenRouter
8.7 s via Google AI Studio, 30-minute median

Benchmarks: 73 of 222 measured

The tick on a coding bar is the median of every model measured on it. Outside coding, the place is this model's rank on that board. A board that never ran the model says so.

Coding index

86.6
  • Terminal-Bench 4 (Vals AI) 63.1% (Mini-SWE-agent) 84 of 100
  • Vibe Code Bench (Vals AI) 89.1% (OpenHands) 89 of 100
  • LiveBench coding 91.0% 91 of 100
  • SWE-bench Verified (Vals AI) Not measured
  • FrontierCode Not measured
  • LMArena WebDev Elo, scaled from 1200 to 1900 1768 Elo (High) 81 of 100

The index averages only the coding benchmarks that have a result; the others are skipped, never filled in. How it is weighted

Other public boards

All rankings

Coding9 of 46 boards

3 more coding boards

Not measured on Aider polyglot, SWE-bench Verified, SWE-bench Lite, SWE-bench (full test set), SWE-bench Multimodal, SWE-bench Multilingual, AA Coding Index, LiveCodeBench (Vals AI), Code migration (Vals AI), ProgramBench (Vals AI), IOI (Vals AI), Terminal-Bench 2.1 (Vals AI), SWE-bench Multimodal (Vals AI), Vibe Code Bench 1-100 (Vals AI), SkillsBench (Vals AI), CyberBench (Vals AI), LiveCodeBench (Artificial Analysis run), SciCode, Terminal-Bench Hard (Artificial Analysis run), Terminal-Bench, DeepSWE, GSO-Bench, WeirdML, MirrorCode, Cybench, LMArena WebDev: from an image, SciCode, SWE-Bench Pro V2, SWE Atlas: Codebase QnA, SWE Atlas: Refactoring, SWE Atlas: Test Writing, GameBench 2, Terminal-Bench 2.0, Terminal-Bench 2.1, Terminal-Bench 3.0, Terminal-Bench 4.0, ProgramBench

Intelligence2 of 2 boards

Agentic work10 of 44 boards

4 more agentic work boards

Not measured on AA Agentic Index, Design Arena: agents building web apps, Design Arena: agents building full-stack apps, Design Arena: agents building Android apps, Design Arena: agents building Godot games, Design Arena: agents building games, Design Arena: HTML slides, Design Arena: PowerPoint slides, SREBench (Vals AI), Finance Agent (Vals AI), Excel Modeling Benchmark (Vals AI), BioMysteryBench (Vals AI), Terminal-Bench-Science (Vals AI), Vals Science Index, Time Horizon Index (Vals AI), CUA-bench (Vals AI), Robo-bench (Vals AI), τ²-Bench Telecom, METR time horizons, Remote Labor Index, GDPval, OSWorld 2.0, BALROG, DeepResearch Bench, PostTrainBench, TheAgentCompany, OSWorld, SpireClimb, LMArena Search, Berkeley Function Calling Leaderboard (BFCL), BrowseComp-Plus, MCP Atlas, Toolathlon-Verified, τ³-Banking

Reasoning13 of 26 boards

7 more reasoning boards

Not measured on GPQA Diamond, MysteryMechanism (Vals AI), MMMU Pro (Vals AI), GPQA Diamond (Artificial Analysis run), Humanity's Last Exam (Artificial Analysis run), Humanity's Last Exam, VPCT, BIG-Bench Hard, LMArena Vision: diagrams, LMArena Vision: homework, Kagi LLM Benchmark, Humanity's Last Exam (Scale run), GoBench

Math5 of 14 boards

Not measured on AIME, MATH 500 (Vals AI), MGSM (Vals AI), AA Math Index, AIME 2025 (Artificial Analysis run), ProofBench, MATH level 5, GSM8K, LMArena Text: math

Knowledge8 of 21 boards

2 more knowledge boards

Not measured on MMLU Pro, LegalBench (Vals AI), CaseLaw (Vals AI), CorpFin (Vals AI), TaxEval (Vals AI), MortgageTax (Vals AI), MedQA (Vals AI), MedCode (Vals AI), MMLU Pro (Artificial Analysis run), MMLU, GeoBench, AI2 Reasoning Challenge, PRBench Finance

Web design6 of 9 boards

Not measured on Design Arena: data viz, Design Arena: SVG, Design Arena: ASCII art

General16 of 49 boards

10 more general boards

Not measured on Public Benefits Bench (Vals AI), SAGE (Vals AI), MedScribe (Vals AI), Vals Multimodal Index, IFBench, DTBench, LMCA, Fiction.LiveBench, Creative writing (Lech Mazur), CL-bench, Surface Evolver Bench, ExploitBench, HellaSwag, WinoGrande, PIQA, CL-bench Life, LMArena Vision, LMArena Text: German, LMArena Text: Japanese, LMArena Text: Korean, LMArena Text: French, LMArena Text: Spanish, LMArena Text: Polish, LMArena Vision: English, LMArena Vision: Chinese, LMArena Vision: reading text, LMArena Vision: humor, LMArena Vision: captioning, LMArena Vision: recognizing things, LMArena Vision: creative writing, LMArena Document, MultiChallenge, EQ-Bench 4

Image generation0 of 5 boards

Not measured on Design Arena: images, Design Arena: graphic design, Design Arena: logos, LMArena Text to Image, LMArena Image Edit

Public boards shown as published (Vals AI, Artificial Analysis, Design Arena) and kept out of the coding index. Each links to its source on the benchmark page.
All 222 benchmarks as a table
Benchmark results for Google Gemini 4 Carbon
BenchmarkResultIndex weight
Aider polyglotCoding Not measured Not in index
SWE-bench VerifiedCoding Not measured Not in index
SWE-bench LiteCoding Not measured Not in index
SWE-bench (full test set)Coding Not measured Not in index
SWE-bench MultimodalCoding Not measured Not in index
SWE-bench MultilingualCoding Not measured Not in index
LiveBench codingCoding 91.0% 15%
LMArena WebDevCoding 1768(High) 10%
Vals IndexGeneral 70.5% Not in index
GPQA DiamondReasoning Not measured Not in index
AIMEMath Not measured Not in index
MMLU ProKnowledge Not measured Not in index
AA Intelligence IndexIntelligence 60.0 Not in index
AA Coding IndexCoding Not measured Not in index
AA Agentic IndexAgentic work Not measured Not in index
Design Arena: websitesWeb design 1319 Not in index
Design Arena: UI componentsWeb design 1357 Not in index
Design Arena: game devWeb design 1326 Not in index
Design Arena: data vizWeb design Not measured Not in index
Design Arena: 3DWeb design 1434 Not in index
Design Arena: all code categoriesWeb design 1348 Not in index
Design Arena: SVGWeb design Not measured Not in index
Design Arena: ASCII artWeb design Not measured Not in index
Design Arena: agents building web appsAgentic work Not measured Not in index
Design Arena: agents building full-stack appsAgentic work Not measured Not in index
Design Arena: agents building mobile appsAgentic work 1284 Not in index
Design Arena: agents building Android appsAgentic work Not measured Not in index
Design Arena: agents building Godot gamesAgentic work Not measured Not in index
Design Arena: agents building gamesAgentic work Not measured Not in index
Design Arena: HTML slidesAgentic work Not measured Not in index
Design Arena: PowerPoint slidesAgentic work Not measured Not in index
Design Arena: spreadsheetsAgentic work 1224 Not in index
Design Arena: imagesImage generation Not measured Not in index
Design Arena: graphic designImage generation Not measured Not in index
Design Arena: logosImage generation Not measured Not in index
LiveBench reasoningReasoning 90.6% Not in index
LiveBench data analysisGeneral 86.5% Not in index
LiveBench researchAgentic work 92.5% Not in index
LiveBench browserAgentic work 80.0% Not in index
LiveBench long agenticAgentic work 72.7% Not in index
LiveBench designWeb design 80.2% Not in index
LiveCodeBench (Vals AI)Coding Not measured Not in index
SWE-bench Verified (Vals AI)Coding Not measured 15%
Terminal-Bench 4 (Vals AI)Coding 63.1%(Mini-SWE-agent) 25%
Vibe Code Bench (Vals AI)Coding 89.1%(OpenHands) 20%
Code migration (Vals AI)Coding Not measured Not in index
ProgramBench (Vals AI)Coding Not measured Not in index
SREBench (Vals AI)Agentic work Not measured Not in index
IOI (Vals AI)Coding Not measured Not in index
Terminal-Bench 2.1 (Vals AI)Coding Not measured Not in index
SWE-bench Multimodal (Vals AI)Coding Not measured Not in index
Vibe Code Bench 1-100 (Vals AI)Coding Not measured Not in index
SkillsBench (Vals AI)Coding Not measured Not in index
CyberBench (Vals AI)Coding Not measured Not in index
Finance Agent (Vals AI)Agentic work Not measured Not in index
Tax Agent Bench (Vals AI)Agentic work 51.8% Not in index
Legal Research Bench (Vals AI)Agentic work 55.8% Not in index
Harvey's Legal Agent Benchmark (Vals AI)Agentic work 17.5% Not in index
Excel Modeling Benchmark (Vals AI)Agentic work Not measured Not in index
BioMysteryBench (Vals AI)Agentic work Not measured Not in index
Terminal-Bench-Science (Vals AI)Agentic work Not measured Not in index
Vals Science IndexAgentic work Not measured Not in index
Time Horizon Index (Vals AI)Agentic work Not measured Not in index
CUA-bench (Vals AI)Agentic work Not measured Not in index
Robo-bench (Vals AI)Agentic work Not measured Not in index
Public Benefits Bench (Vals AI)General Not measured Not in index
MysteryMechanism (Vals AI)Reasoning Not measured Not in index
MMMU Pro (Vals AI)Reasoning Not measured Not in index
MATH 500 (Vals AI)Math Not measured Not in index
MGSM (Vals AI)Math Not measured Not in index
SAGE (Vals AI)General Not measured Not in index
LegalBench (Vals AI)Knowledge Not measured Not in index
CaseLaw (Vals AI)Knowledge Not measured Not in index
CorpFin (Vals AI)Knowledge Not measured Not in index
TaxEval (Vals AI)Knowledge Not measured Not in index
MortgageTax (Vals AI)Knowledge Not measured Not in index
MedQA (Vals AI)Knowledge Not measured Not in index
MedCode (Vals AI)Knowledge Not measured Not in index
MedScribe (Vals AI)General Not measured Not in index
Vals Multimodal IndexGeneral Not measured Not in index
AA Math IndexMath Not measured Not in index
GPQA Diamond (Artificial Analysis run)Reasoning Not measured Not in index
Humanity's Last Exam (Artificial Analysis run)Reasoning Not measured Not in index
MMLU Pro (Artificial Analysis run)Knowledge Not measured Not in index
LiveCodeBench (Artificial Analysis run)Coding Not measured Not in index
SciCodeCoding Not measured Not in index
Terminal-Bench Hard (Artificial Analysis run)Coding Not measured Not in index
IFBenchGeneral Not measured Not in index
Long context reasoning (AA-LCR)General 79.3%(High) Not in index
τ²-Bench TelecomAgentic work Not measured Not in index
AIME 2025 (Artificial Analysis run)Math Not measured Not in index
Terminal-Bench 4.0 (Artificial Analysis run)Coding 65.2%(High) Not in index
FrontierCode 2.0Coding 40.6%(High) Not in index
HLE-Diamond (Artificial Analysis run)Reasoning 69.1%(High) Not in index
GDPval-AAGeneral 1733(High) Not in index
AA-OmniscienceKnowledge 53.5(High) Not in index
CritPt v2, hard subset (Artificial Analysis run)Reasoning 69.0%(High) Not in index
Terminal-BenchCoding Not measured Not in index
DeepSWECoding Not measured Not in index
FrontierCodeCoding Not measured 15%
FrontierSWECoding 61.2%(High) Not in index
GSO-BenchCoding Not measured Not in index
WeirdMLCoding Not measured Not in index
MirrorCodeCoding Not measured Not in index
APEX-AgentsAgentic work 84.2% Not in index
METR time horizonsAgentic work Not measured Not in index
Remote Labor IndexAgentic work Not measured Not in index
GDPvalAgentic work Not measured Not in index
OSWorld 2.0Agentic work Not measured Not in index
BALROGAgentic work Not measured Not in index
DeepResearch BenchAgentic work Not measured Not in index
PostTrainBenchAgentic work Not measured Not in index
GPQA Diamond (Epoch AI run)Reasoning 96.5%(High) Not in index
ARC-AGIReasoning 98.5%(Medium) Not in index
ARC-AGI-2Reasoning 94.2%(Medium) Not in index
Humanity's Last ExamReasoning Not measured Not in index
SimpleBenchReasoning 92.6% Not in index
Chess puzzlesReasoning 78.0%(High) Not in index
Mystery game puzzlesReasoning 73.0%(High) Not in index
EBR-benchReasoning 87.6%(High) Not in index
OTIS Mock AIMEMath 100.0%(High) Not in index
FrontierMath, tiers 1 to 3Math 90.5%(High) Not in index
FrontierMath, tier 4Math 95.1%(High) Not in index
ProofBenchMath Not measured Not in index
MATH level 5Math Not measured Not in index
GSM8KMath Not measured Not in index
SimpleQA VerifiedKnowledge 77.7%(High) Not in index
MMLUKnowledge Not measured Not in index
GeoBenchKnowledge Not measured Not in index
DTBenchGeneral Not measured Not in index
LMCAGeneral Not measured Not in index
Fiction.LiveBenchGeneral Not measured Not in index
Creative writing (Lech Mazur)General Not measured Not in index
CL-benchGeneral Not measured Not in index
Surface Evolver BenchGeneral Not measured Not in index
Furniture assemblyGeneral 77.5%(High) Not in index
ExploitBenchGeneral Not measured Not in index
CybenchCoding Not measured Not in index
TheAgentCompanyAgentic work Not measured Not in index
OSWorldAgentic work Not measured Not in index
SpireClimbAgentic work Not measured Not in index
VPCTReasoning Not measured Not in index
BIG-Bench HardReasoning Not measured Not in index
AI2 Reasoning ChallengeKnowledge Not measured Not in index
HellaSwagGeneral Not measured Not in index
WinoGrandeGeneral Not measured Not in index
PIQAGeneral Not measured Not in index
CL-bench LifeGeneral Not measured Not in index
ALE-BenchCoding 2374.7(High) Not in index
Vending-Bench 2Agentic work $16,484 Not in index
Epoch Capabilities IndexIntelligence 169.8 Not in index
LMArena TextGeneral 1538(High) Not in index
LMArena Text: codingCoding 1564(High) Not in index
LMArena Text: hard promptsReasoning 1551(High) Not in index
LMArena Text: mathMath Not measured Not in index
LMArena Text: instruction followingGeneral 1539(High) Not in index
LMArena Text: creative writingGeneral 1533(High) Not in index
LMArena VisionGeneral Not measured Not in index
LMArena Text: EnglishGeneral 1530(High) Not in index
LMArena Text: non-EnglishGeneral 1534(High) Not in index
LMArena Text: ChineseGeneral 1613(High) Not in index
LMArena Text: GermanGeneral Not measured Not in index
LMArena Text: JapaneseGeneral Not measured Not in index
LMArena Text: KoreanGeneral Not measured Not in index
LMArena Text: FrenchGeneral Not measured Not in index
LMArena Text: SpanishGeneral Not measured Not in index
LMArena Text: RussianGeneral 1560(High) Not in index
LMArena Text: PolishGeneral Not measured Not in index
LMArena Text: multi-turnGeneral 1569(High) Not in index
LMArena Text: longer queriesGeneral 1549(High) Not in index
LMArena Text: expertReasoning 1582(High) Not in index
LMArena Text: hard prompts in EnglishReasoning 1545(High) Not in index
LMArena Text: software and ITCoding 1552(High) Not in index
LMArena Text: mathematical workMath 1538(High) Not in index
LMArena Text: scienceKnowledge 1535(High) Not in index
LMArena Text: medicine and healthcareKnowledge 1525(High) Not in index
LMArena Text: legal and governmentKnowledge 1542(High) Not in index
LMArena Text: business and financeKnowledge 1520(High) Not in index
LMArena Text: writing and languageGeneral 1542(High) Not in index
LMArena Text: entertainment and mediaGeneral 1527(High) Not in index
LMArena WebDev: ReactCoding 1792(High) Not in index
LMArena WebDev: HTMLCoding 1770(High) Not in index
LMArena WebDev: from an imageCoding Not measured Not in index
LMArena Vision: EnglishGeneral Not measured Not in index
LMArena Vision: ChineseGeneral Not measured Not in index
LMArena Vision: reading textGeneral Not measured Not in index
LMArena Vision: diagramsReasoning Not measured Not in index
LMArena Vision: homeworkReasoning Not measured Not in index
LMArena Vision: humorGeneral Not measured Not in index
LMArena Vision: captioningGeneral Not measured Not in index
LMArena Vision: recognizing thingsGeneral Not measured Not in index
LMArena Vision: creative writingGeneral Not measured Not in index
LMArena SearchAgentic work Not measured Not in index
LMArena DocumentGeneral Not measured Not in index
LMArena Text to ImageImage generation Not measured Not in index
LMArena Image EditImage generation Not measured Not in index
Berkeley Function Calling Leaderboard (BFCL)Agentic work Not measured Not in index
Kagi LLM BenchmarkReasoning Not measured Not in index
BrowseComp-PlusAgentic work Not measured Not in index
SciCodeCoding Not measured Not in index
FACTS Benchmark SuiteKnowledge 78.4% Not in index
MathArenaMath 85.4%(high) Not in index
MultiChallengeGeneral Not measured Not in index
MCP AtlasAgentic work Not measured Not in index
Humanity's Last Exam (Scale run)Reasoning Not measured Not in index
PRBench FinanceKnowledge Not measured Not in index
PRBench LegalKnowledge 53.3% Not in index
SWE-Bench Pro V2Coding Not measured Not in index
SWE Atlas: Codebase QnACoding Not measured Not in index
SWE Atlas: RefactoringCoding Not measured Not in index
SWE Atlas: Test WritingCoding Not measured Not in index
EQ-Bench 4General Not measured Not in index
GameBench 2Coding Not measured Not in index
GoBenchReasoning Not measured Not in index
Terminal-Bench 2.0Coding Not measured Not in index
Terminal-Bench 2.1Coding Not measured Not in index
Terminal-Bench 3.0Coding Not measured Not in index
Terminal-Bench 4.0Coding Not measured Not in index
CursorBench 4.0Coding 60.4%(high) Not in index
Toolathlon-VerifiedAgentic work Not measured Not in index
ProgramBenchCoding Not measured Not in index
τ³-BankingAgentic work Not measured Not in index

Scores by reasoning effort

Some boards test this model at more than one reasoning effort. Rankings use its best run; every run the source published is listed here.

Scores by reasoning effort
BenchmarkEffortScoreSource
AA-Omniscience High · used in rankings 53.5 Artificial Analysis
AA-Omniscience Medium 46.8 Artificial Analysis
AA-Omniscience Low 39.2 Artificial Analysis
ARC-AGI Medium · used in rankings 98.5% Epoch AI benchmarking hub
ARC-AGI High 97.5% Epoch AI benchmarking hub
ARC-AGI Low 85.5% Epoch AI benchmarking hub
ARC-AGI-2 Medium · used in rankings 94.2% Epoch AI benchmarking hub
ARC-AGI-2 High 92.1% Epoch AI benchmarking hub
ARC-AGI-2 Low 49.6% Epoch AI benchmarking hub
CritPt v2, hard subset (Artificial Analysis run) High · used in rankings 69.0% Artificial Analysis
CritPt v2, hard subset (Artificial Analysis run) Medium 69.0% Artificial Analysis
CritPt v2, hard subset (Artificial Analysis run) Low 65.0% Artificial Analysis
CursorBench 4.0 high · used in rankings 60.4% CursorBench (Cursor)
CursorBench 4.0 medium 60.1% CursorBench (Cursor)
CursorBench 4.0 low 58.6% CursorBench (Cursor)
FrontierCode 2.0 High · used in rankings 40.6% Artificial Analysis
FrontierCode 2.0 Medium 39.5% Artificial Analysis
FrontierCode 2.0 Low 29.6% Artificial Analysis
HLE-Diamond (Artificial Analysis run) High · used in rankings 69.1% Artificial Analysis
HLE-Diamond (Artificial Analysis run) Medium 67.4% Artificial Analysis
HLE-Diamond (Artificial Analysis run) Low 61.9% Artificial Analysis
Terminal-Bench 4.0 (Artificial Analysis run) High · used in rankings 65.2% Artificial Analysis
Terminal-Bench 4.0 (Artificial Analysis run) Low 62.6% Artificial Analysis
Terminal-Bench 4.0 (Artificial Analysis run) Medium 60.6% Artificial Analysis

What it costs

A list price says what a token costs. The cost per solved task says what a working answer costs, which is the number that decides.

Output price against the market

Gemini 4 Carbon pricing
$0.045Dashed line: median $1.90, log scale$180.00
$10.00 per million output tokens is cheaper than 14% of the 338 paid models in the catalog.

Cost per solved task

How it is computed

Neither board that publishes what a SWE-bench Verified attempt costs, Vals AI and swebench.com, has run this model. We leave the number out rather than estimate it.

LiveBench, on its own coding tasks, publishes what one task cost this model: $6.462, at a score of 91.0%. LiveBench counts that as $7.102 per successful task. Different tasks from SWE-bench, so it is not our number and does not enter its ranking. LiveBench coding

What the boards say about its runs

Beside a result, many boards publish what the run cost, how long it took, the tokens it spent or the votes behind a rating. Each figure as its board printed it, one board per row.

What each board publishes about the runs behind Google: Gemini 4 Carbon's results
BoardResultWhat the run costAlso published
LiveBench coding 91.0% $6.4624 per task Output tokens per task 106,420
Vals Index 70.5% $10.51 per test Nothing else
LiveBench reasoning 90.6% $0.2333 per task Output tokens per task 21,641
LiveBench data analysis 86.5% $0.7056 per task Output tokens per task 56,034
LiveBench research 92.5% $5.0034 per task Output tokens per task 116,829
LiveBench browser 80.0% $7.0366 per task Output tokens per task 31,005
LiveBench long agentic 72.7% $9.0549 per task Output tokens per task 310,037
LiveBench design 80.2% $1.2244 per task Output tokens per task 70,819
Terminal-Bench 4 (Vals AI) 63.1%(Mini-SWE-agent) $7.45 per test Nothing else
Vibe Code Bench (Vals AI) 89.1%(OpenHands) $8.25 per test Nothing else
Tax Agent Bench (Vals AI) 51.8% $6.34 per test Nothing else
Legal Research Bench (Vals AI) 55.8% $8.74 per test Nothing else
36 more boards
What each board publishes about the runs behind Google: Gemini 4 Carbon's results, continued
Harvey's Legal Agent Benchmark (Vals AI) 17.5% $6.52 per test Nothing else
FrontierSWE 61.2%(High) $61.93 average cost per task Best of 5 runs 66.7% · Hours per task 12.6 h
ALE-Bench 2374.7(High) $2.0683 per problem Tokens per problem 164,711
MathArena 85.4%(high) $15.6955 expected cost per problem Nothing else
LMArena WebDev 1768 Elo(High) Not published Votes 2,120 · Interval (±) ±15.3
Design Arena: websites 1319 Elo Not published Battles 1,119
Design Arena: UI components 1357 Elo Not published Battles 204
Design Arena: game dev 1326 Elo Not published Battles 595
Design Arena: 3D 1434 Elo Not published Battles 553
Design Arena: all code categories 1348 Elo Not published Battles 2,178
Design Arena: agents building mobile apps 1284 Elo Not published Battles 186
Design Arena: spreadsheets 1224 Elo Not published Battles 173
APEX-Agents 84.2% Not published Mean score 90.4%
LMArena Text 1538 Elo(High) Not published Votes 4,273 · Interval (±) ±9.6
LMArena Text: coding 1564 Elo(High) Not published Votes 1,069 · Interval (±) ±18.6
LMArena Text: hard prompts 1551 Elo(High) Not published Votes 2,671 · Interval (±) ±12.0
LMArena Text: instruction following 1539 Elo(High) Not published Votes 1,421 · Interval (±) ±16.4
LMArena Text: creative writing 1533 Elo(High) Not published Votes 1,007 · Interval (±) ±20.0
LMArena Text: English 1530 Elo(High) Not published Votes 1,495 · Interval (±) ±15.9
LMArena Text: non-English 1534 Elo(High) Not published Votes 2,778 · Interval (±) ±11.8
LMArena Text: Chinese 1613 Elo(High) Not published Votes 426 · Interval (±) ±29.4
LMArena Text: Russian 1560 Elo(High) Not published Votes 635 · Interval (±) ±24.1
LMArena Text: multi-turn 1569 Elo(High) Not published Votes 605 · Interval (±) ±25.4
LMArena Text: longer queries 1549 Elo(High) Not published Votes 1,862 · Interval (±) ±14.7
LMArena Text: expert 1582 Elo(High) Not published Votes 399 · Interval (±) ±29.7
LMArena Text: hard prompts in English 1545 Elo(High) Not published Votes 981 · Interval (±) ±19.7
LMArena Text: software and IT 1552 Elo(High) Not published Votes 1,580 · Interval (±) ±15.3
LMArena Text: mathematical work 1538 Elo(High) Not published Votes 237 · Interval (±) ±39.7
LMArena Text: science 1535 Elo(High) Not published Votes 631 · Interval (±) ±24.0
LMArena Text: medicine and healthcare 1525 Elo(High) Not published Votes 274 · Interval (±) ±37.0
LMArena Text: legal and government 1542 Elo(High) Not published Votes 283 · Interval (±) ±36.4
LMArena Text: business and finance 1520 Elo(High) Not published Votes 715 · Interval (±) ±22.2
LMArena Text: writing and language 1542 Elo(High) Not published Votes 1,262 · Interval (±) ±17.9
LMArena Text: entertainment and media 1527 Elo(High) Not published Votes 1,167 · Interval (±) ±18.4
LMArena WebDev: React 1792 Elo(High) Not published Votes 1,551 · Interval (±) ±18.2
LMArena WebDev: HTML 1770 Elo(High) Not published Votes 217 · Interval (±) ±52.0

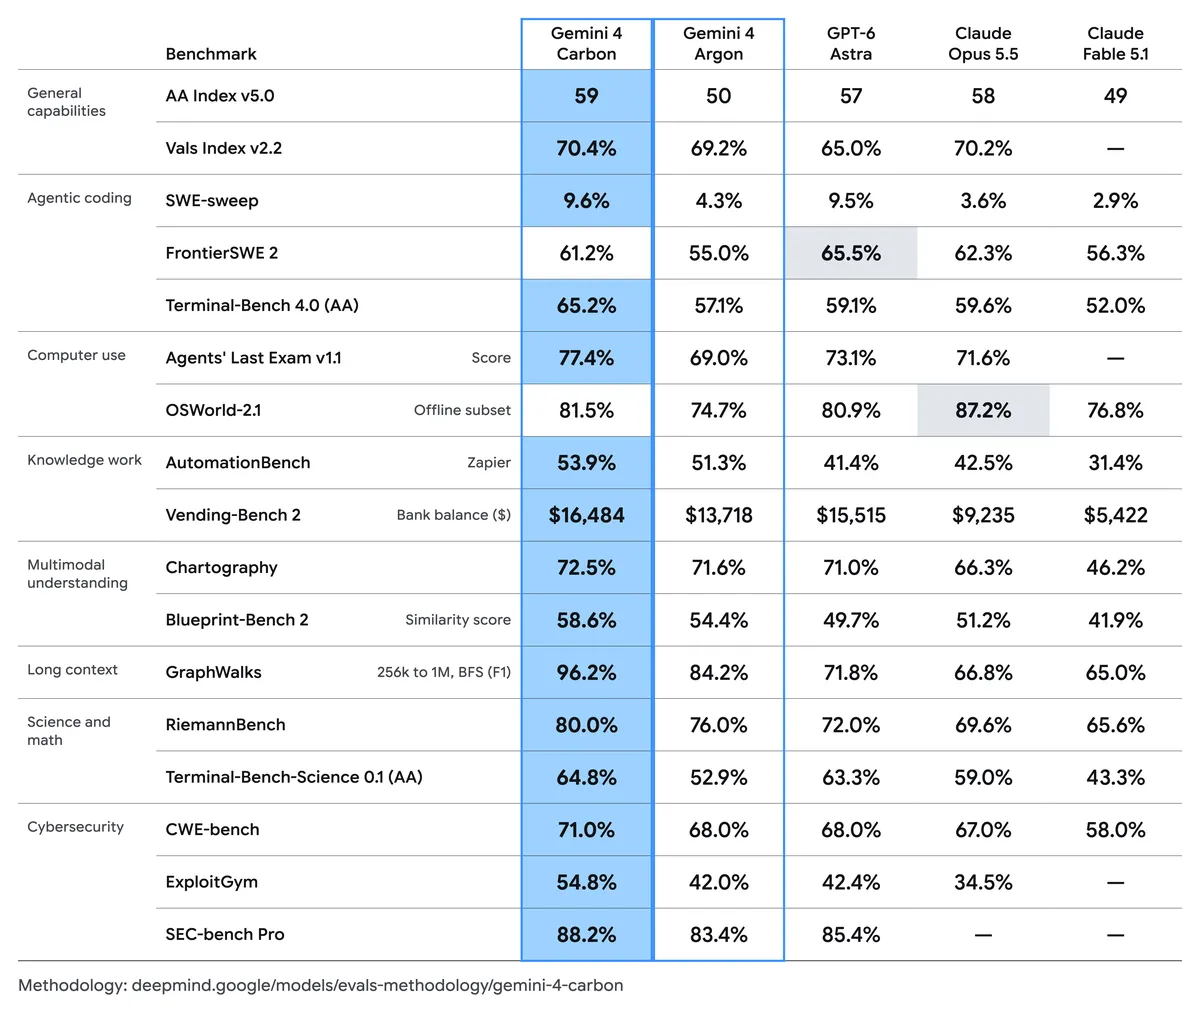
Results Google reported at launch

Google published these results in “Gemini 4 Carbon: our next frontier model” on October 28, 2026. They are the maker's own numbers, not independent measurements, and they do not count toward the LLMBenchmark Index.

Results Google reported for this model
BenchmarkScoreSettingSource
AA Index v5.0 59 Not published October 28, 2026 · read from the maker's chart
Agents' Last Exam v1.1 77.4% Score October 28, 2026 · read from the maker's chart
AutomationBench 53.9% Zapier October 28, 2026 · read from the maker's chart
Blueprint-Bench 2 58.6% Similarity score October 28, 2026 · read from the maker's chart
Chartography 72.5 Not published October 28, 2026 · read from the maker's chart
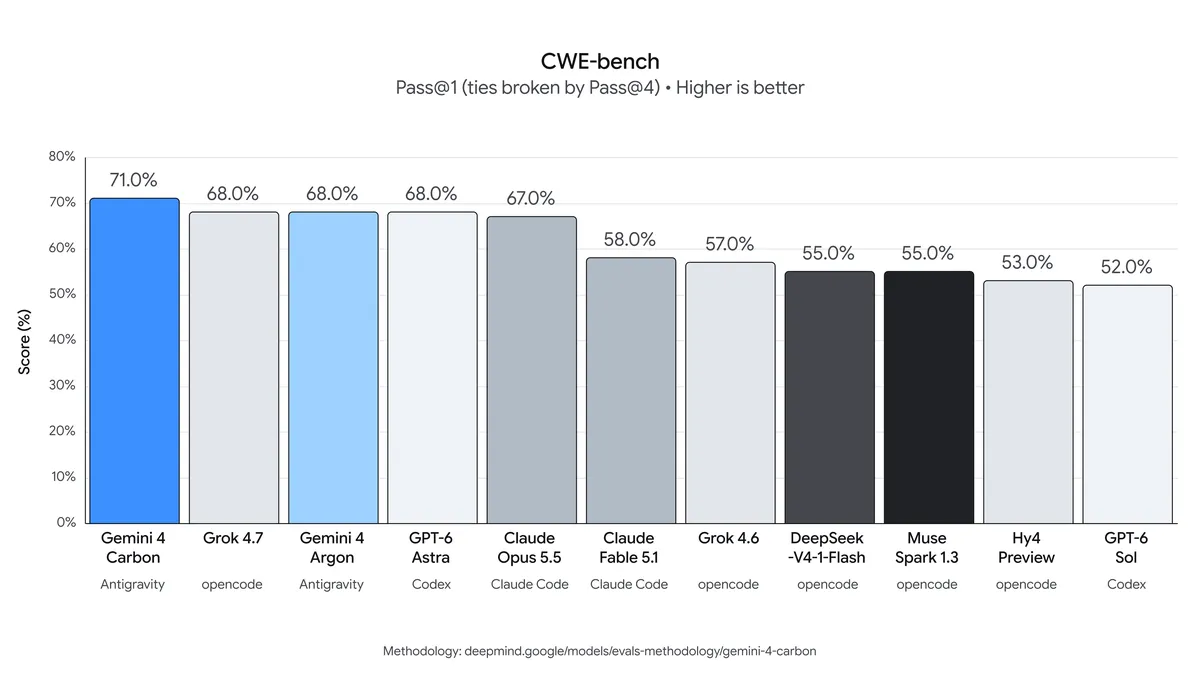
CWE-bench 71.0% Not published October 28, 2026 · read from the maker's chart
CWE-bench 71.0% Pass@1 (ties broken by Pass@4); Antigravity October 28, 2026 · read from the maker's chart
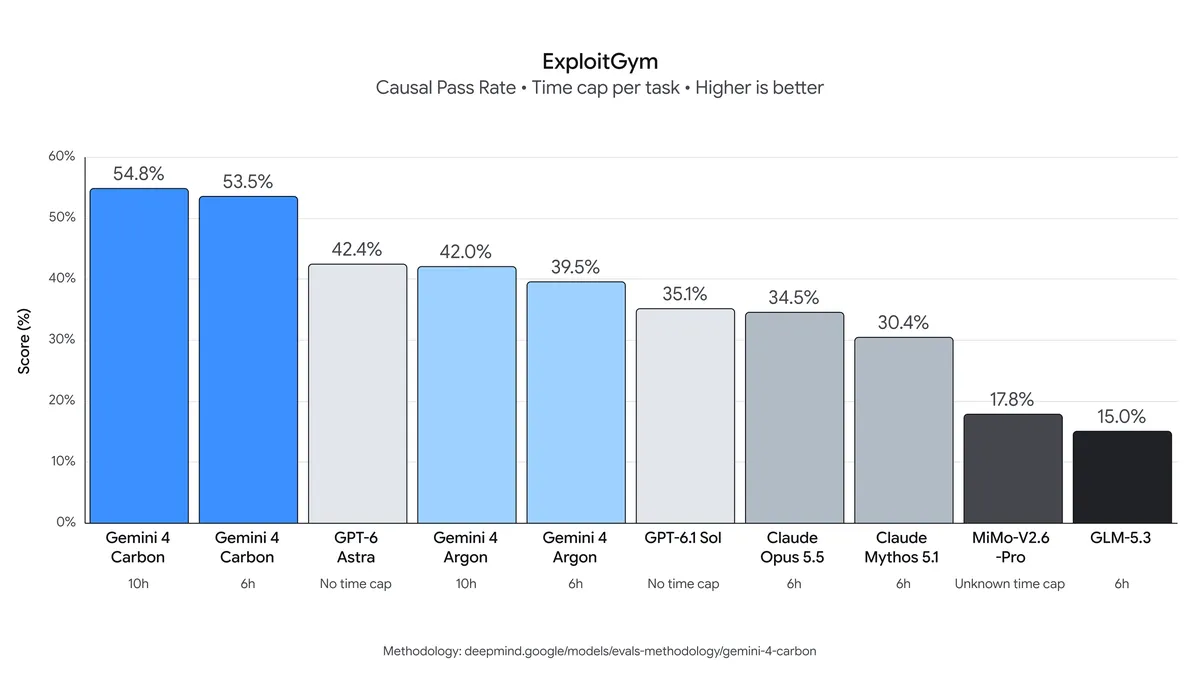
ExploitGym 54.8% Not published October 28, 2026 · read from the maker's chart
ExploitGym 54.8% 10h October 28, 2026 · read from the maker's chart
ExploitGym 53.5% 6h October 28, 2026 · read from the maker's chart
FrontierSWE v2 61.2% Not published October 28, 2026 · read from the maker's chart
GraphWalks 96.2% 256k to 1M, BFS (F1) October 28, 2026 · read from the maker's chart
OSWorld 2.1 81.5% Offline subset October 28, 2026 · read from the maker's chart
RiemannBench 80.0% Not published October 28, 2026 · read from the maker's chart
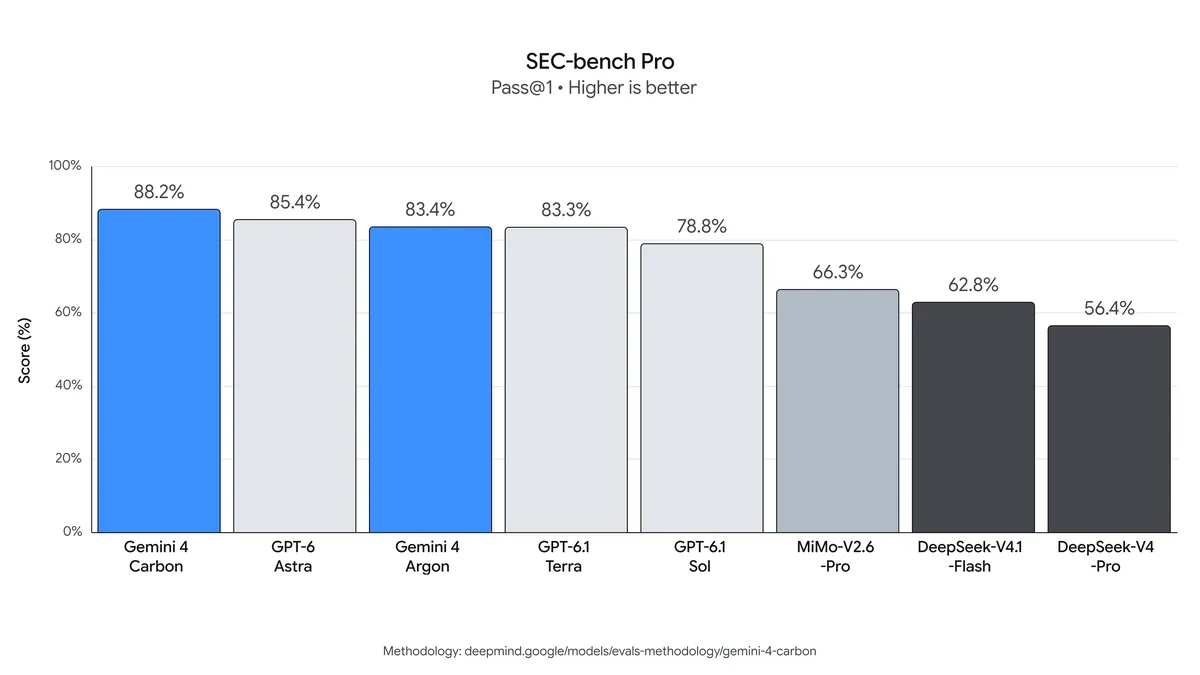
SEC-Bench Pro 88.2% Not published October 28, 2026 · read from the maker's chart
SEC-Bench Pro 88.2% Pass@1 October 28, 2026 · read from the maker's chart
SWE-sweep 9.6% Not published October 28, 2026 · read from the maker's chart
Terminal-Bench 4.0-AA 65.2% Not published October 28, 2026 · read from the maker's chart
Terminal-Bench-Science 0.1 (AA) 64.8% Not published October 28, 2026 · read from the maker's chart
Vals Index v2.2 70.4% Not published October 28, 2026 · read from the maker's chart

Google Gemini 4 Carbon: launch results and current rankings

Google Gemini 4 Carbon API providers

On these lists

Compare with models of a similar score

All 104 comparisons for Gemini 4 Carbon