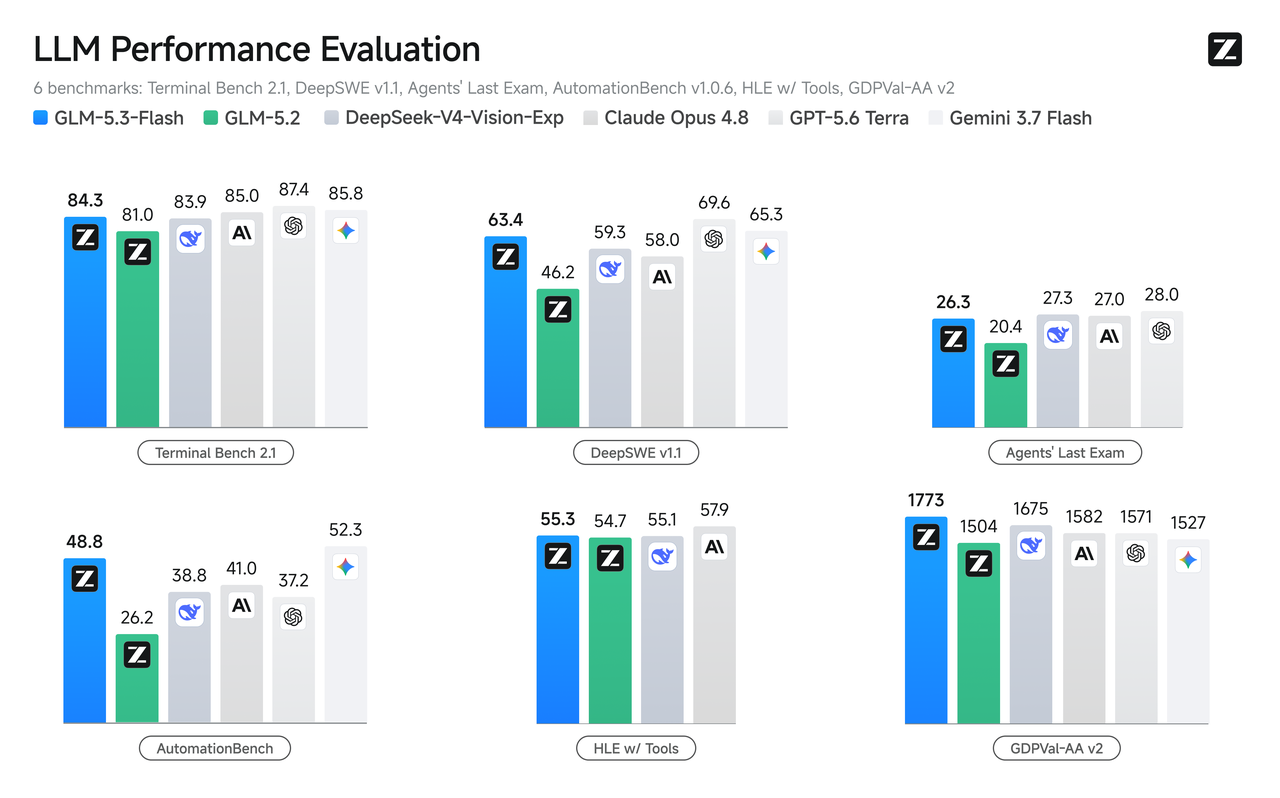
On November 5, 2026, 11 of our catalog's models had a Terminal-Bench 2.1 result, and OpenAI GPT-6 Astra led with 87.4%, ahead of Anthropic Claude Fable 5 at 83.8%.
Terminal-Bench 2.1 gives an AI agent tasks to finish in a real command-line terminal. The number is the accuracy the Terminal-Bench team publishes on its official 2.1 leaderboard: the share of tasks the agent completes. Each version of Terminal-Bench is a different task set, so 2.1 results are not comparable with the other versions.
How to read the score: Each entry on the board is a model run inside an agent harness (Claude Code, Codex, mini-SWE-agent and others), at one reasoning effort. We show the best result per model and name the agent and the effort. The best result can come from an agent the board lists from a third party, not the maker.
Cite this page:LLMBenchmark.ai, "Terminal-Bench 2.1 Leaderboard & Scores (November 2026)", https://llmbenchmark.ai/benchmarks/terminal-bench-2-1, accessed November 5, 2026.
Role in the index
A coding board we show beside the Vibe Coding Index, not inside it: the index keeps the six boards it was defined on, so a score does not move every time a board is added. Read the methodology
Only models in our catalog are listed, and each appears once with its best published run. 62 rows were read from the source on November 5, 2026, and rows that match no catalog model are left out.
Results reported by model makers
The board above is Terminal-Bench (tbench.ai)'s own run. Model makers also report Terminal-Bench 2.1 in their release announcements; those numbers are below, with the date and the announcement. They are not independent and do not count toward any index.
Terminal-Bench 2.1 scores reported by model makers