CursorBench 4.0 leaderboard
- Claude Opus 5.5 leads
- 57.8%
- models measured
- 18
- lead over #2
- +2.3 pts
- median
- 44.5%
Leader on CursorBench 4.0 · read November 5
        # CursorBench 4.0, read November 5
        leaders = {
            "Claude Opus 5.5": 57.8%,    "Claude Sonnet 5.5": 55.5%,    "Gemini 4 Argon": 52.9%,
        }
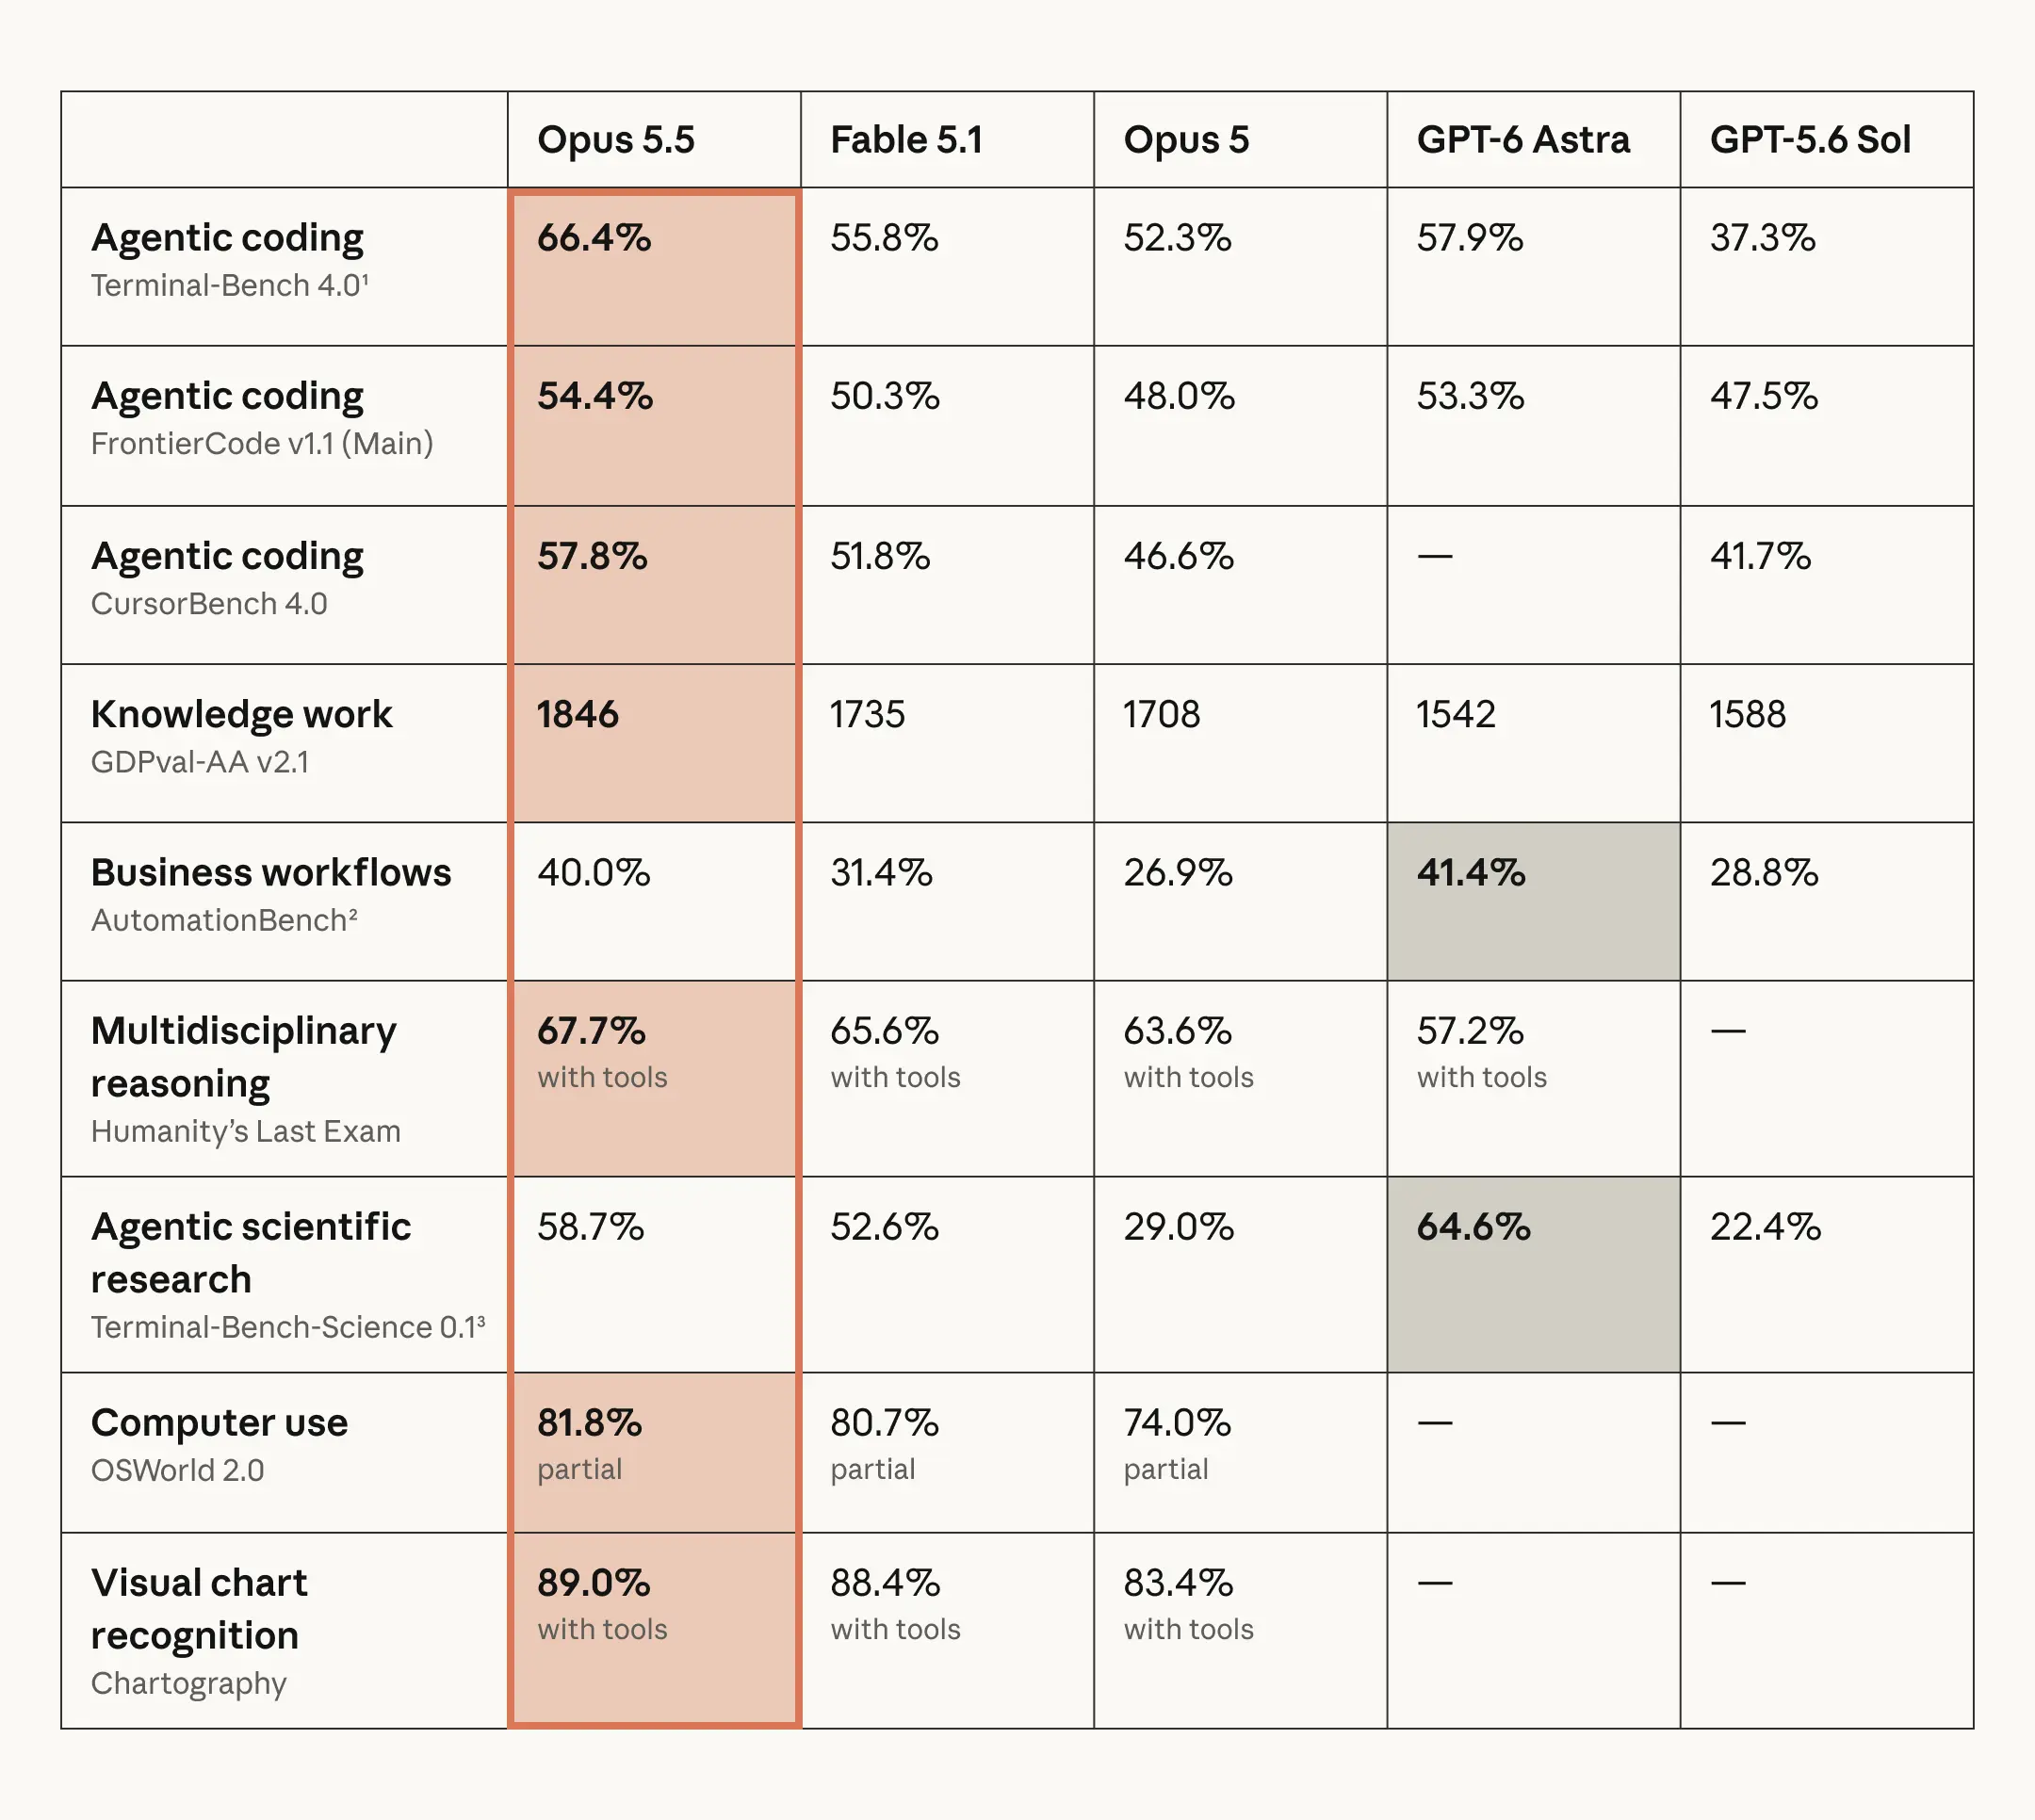
On November 5, 2026, 18 of our catalog's models had a CursorBench 4.0 result, and Anthropic Claude Opus 5.5 led with 57.8%, ahead of Anthropic Claude Sonnet 5.5 at 55.5%.
CursorBench evaluates agents on ambiguous, multi-file tasks taken from real Cursor sessions. The number is the score Cursor publishes for each model on version 4.0; higher is better. Each model appears at several reasoning efforts, such as Max, Extra High and High.
How to read the score: We show the best effort per model.
Role in the index
A coding board we show beside the Vibe Coding Index, not inside it: the index keeps the six boards it was defined on, so a score does not move every time a board is added. Read the methodology
| # | Model | Result | Evidence | Coding index | Output $/Mtok |
|---|---|---|---|---|---|
| 1 | Claude Opus 5.5Anthropic | 57.8% | 88.9 | $20.00 | |
| 2 | Claude Sonnet 5.5Anthropic | 55.5% | 87.3 | $10.00 | |
| 3 | Gemini 4 ArgonGoogle | 52.9% | 81.0 | $10.00 | |
| 4 | Claude Fable 5.1Anthropic | 51.8% | 84.3 | $50.00 | |
| 5 | Muse WonderMeta | 50.4% | 72.0 | $20.00 | |
| 6 | Claude Haiku 5.5Anthropic | 48.4% | 70.8 | $0.50 | |
| 7 | DeepSeek V4.1 Flash 1017DeepSeek | 47.7% | 70.3 | $0.60 | |
| 8 | Claude Opus 5Anthropic | 46.6% | 81.6 | $25.00 | |
| 9 | Grok 4.7xAI | 46.3% | 66.7 | $6.00 | |
| 10 | GLM 5.3Z.ai | 42.6% | 68.5 | $4.40 | |
| 11 | GPT-5.6 SolOpenAI | 41.7% | 70.7 | $20.00 | |
| 12 | Muse Spark 1.3Meta | 41.6% | 57.4 | $4.25 | |
| 13 | Grok 4.6xAI | 41.4% | 65.7 | $6.00 | |
| 14 | GPT-5.6 TerraOpenAI | 41.3% | 63.8 | $12.00 | |
| 15 | Gemini 3.8 FlashGoogle | 39.6% | 61.6 | $3.75 | |
| 16 | GLM 5.3 FlashZ.ai | 36.8% | 57.7 | $0.50 | |
| 17 | GPT-5.6 LunaOpenAI | 35.9% | 55.3 | $1.20 | |
| 18 | Claude Sonnet 5Anthropic | 34.1% | 54.7 | $10.00 |
Only models in our catalog are listed, and each appears once with its best published run. 18 rows were read from the source on November 5, 2026, and rows that match no catalog model are left out.
The board above is CursorBench (Cursor)'s own run. Model makers also report CursorBench 4.0 in their release announcements; those numbers are below, with the date and the announcement. They are not independent and do not count toward any index.
| Rank | Model | Score | Setting | Reported by | Date |
|---|---|---|---|---|---|
| 1 | Claude Opus 5.5 | 57.8% | Not published | Anthropic | May 27, 2026 (model release) · read from the maker's chart |
| 2 | Claude Sonnet 5.5 | 55.5% | Not published | Anthropic | June 30, 2026 (model release) |
| 3 | Claude Fable 5.1 | 51.8% | Not published | Anthropic | May 27, 2026 (model release) · read from the maker's chart |
| 4 | Claude Opus 5 | 46.6% | Not published | Anthropic | May 27, 2026 (model release) · read from the maker's chart |
| 5 | Grok 4.7 | 46.3% | xHigh | xAI | September 21, 2026 |
| 6 | Grok 4.6 | 40.4% | High | xAI | September 21, 2026 |
| 7 | Claude Sonnet 5 | 34.1% | Not published | Anthropic | June 30, 2026 (model release) |