FrontierSWE v2 leaderboard
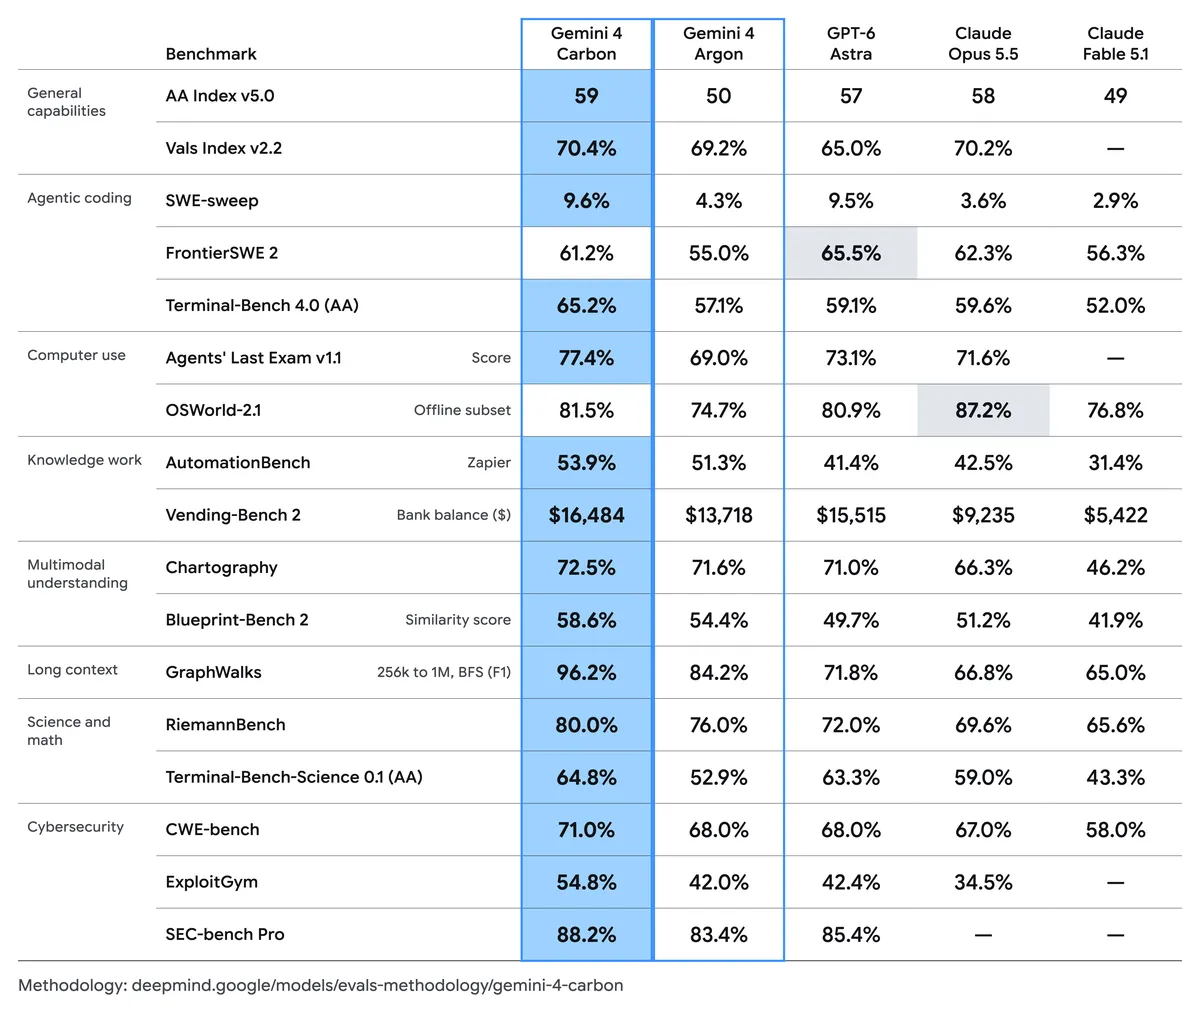
As of November 14, 2026, among the results listed here, Anthropic Claude Fable 5.2 has the highest reported FrontierSWE v2 score, 69.9%, published by Anthropic, ahead of Anthropic Claude Opus 5.5 at 62.3%. 5 models have a FrontierSWE v2 result in our records.
Scores as the model makers published them, not re-run by us; each row links to its announcement.
5 models ranked · 2 makers
| Rank | Model | Score | Setting | Reported by | Date |
|---|---|---|---|---|---|
| 1 | Claude Fable 5.2 | 69.9% | Not published | Anthropic | November 9, 2026 (model release) |
| 2 | Claude Opus 5.5 | 62.3% | Not published | Anthropic | November 9, 2026 (model release) |
| 3 | Gemini 4 Carbon | 61.2% | Not published | October 28, 2026 · read from the maker's chart | |
| 4 | Claude Fable 5.1 | 56.3% | Not published | Anthropic | November 9, 2026 (model release) |
| 5 | Gemini 4 Argon | 55.0% | Not published | October 13, 2026 (model release) |
How much to trust these numbers
- Source
- Reported by the model makers themselves. Not re-run by LLMBenchmark or anyone independent.
- Settings
- All ranked results use the same reported setting.
- Spread
- 69.9% to 55.0% across 5 models.
- Freshness
- Newest result published November 9, 2026; oldest October 13, 2026.
- Charts
- Some values were read from charts in the announcements. Two independent readings had to match exactly.
What FrontierSWE v2 measures
FrontierSWE v2 asks models to complete 34 software engineering tasks with 20-hour agent budgets, and its score is the mean of task scores. Source: FrontierSWE V2