Google Gemini 4 Carbon at launch
- Released November 10, 2026
- 1.05M context
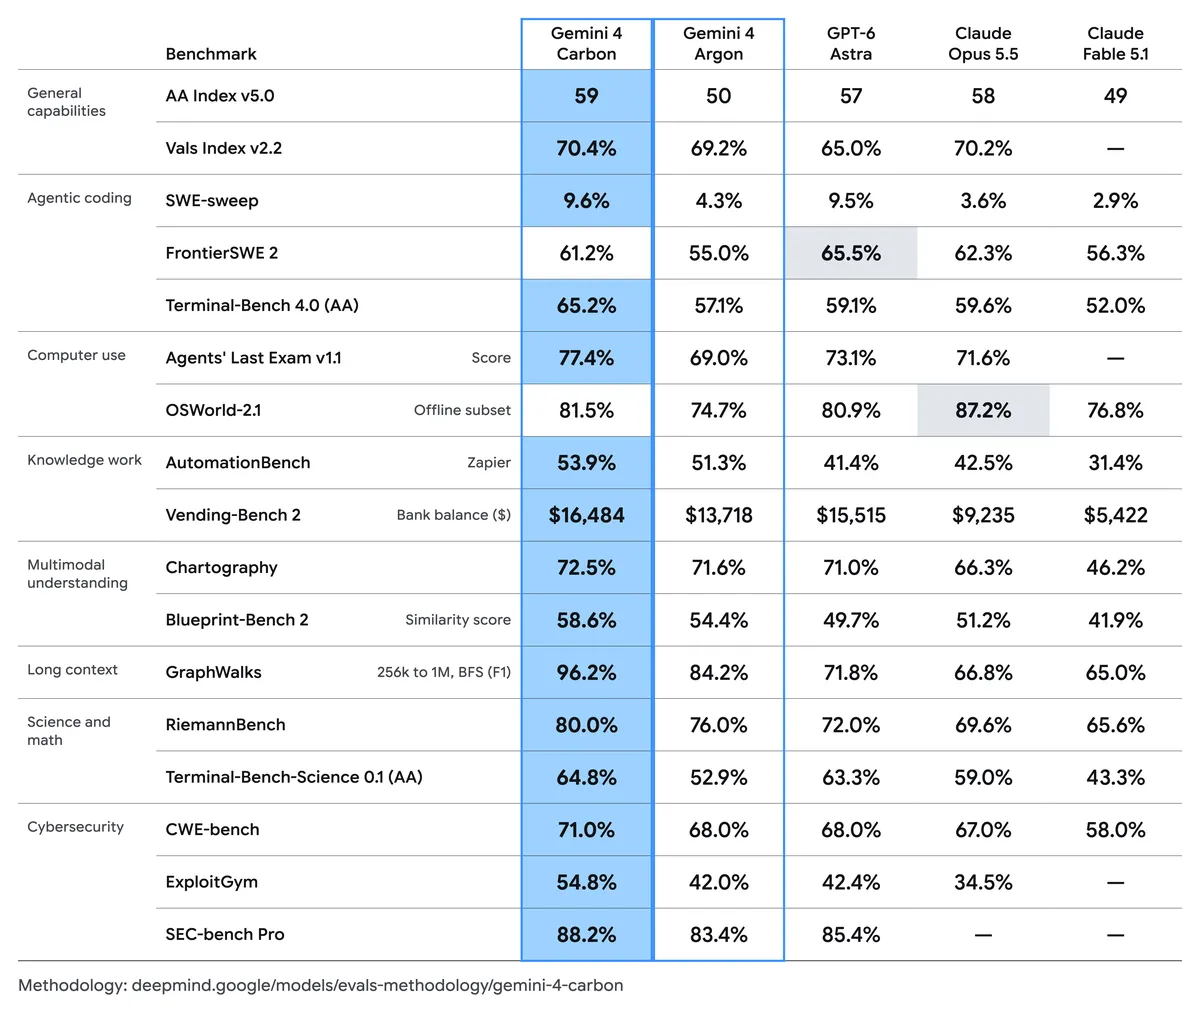
Google released Gemini 4 Carbon on November 10, 2026. As of November 14, 2026, it ranks #2 of 118 models on the LLMBenchmark Index, between Anthropic Claude Fable 5.2 (#1) and Anthropic Claude Opus 5.5 (#3). Google's own announcement reports 20 benchmark results, including AutomationBench (53.9%) and Chartography (72.5). It costs $2.00 per million input tokens and $10.00 per million output tokens on OpenRouter.
What Google reported at launch
From “Gemini 4 Carbon: our next frontier model”, October 28, 2026. The maker's own numbers, not re-run by us.
-
AA Index v5.0
59
#1 of 3 models with a reported result
-
Agents' Last Exam v1.1
77.4%
Score
#1 of 2 models with a reported result
-
AutomationBench
53.9%
Zapier
#2 of 20 models with a reported result
-
Blueprint-Bench 2
58.6%
Similarity score
#1 of 3 models with a reported result
-
Chartography
72.5
#3 of 13 models with a reported result
-
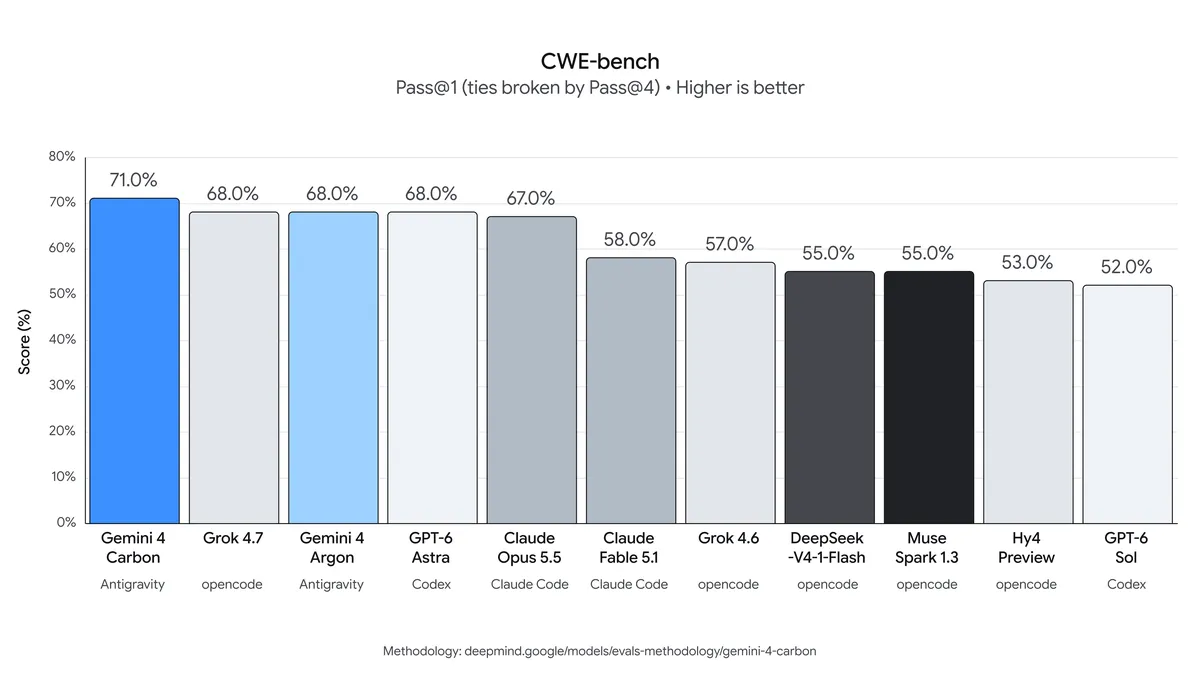
CWE-bench
71.0%
#1 of 2 models with a reported result
-
CWE-bench
71.0%
Pass@1 (ties broken by Pass@4); Antigravity
#1 of 2 models with a reported result
-
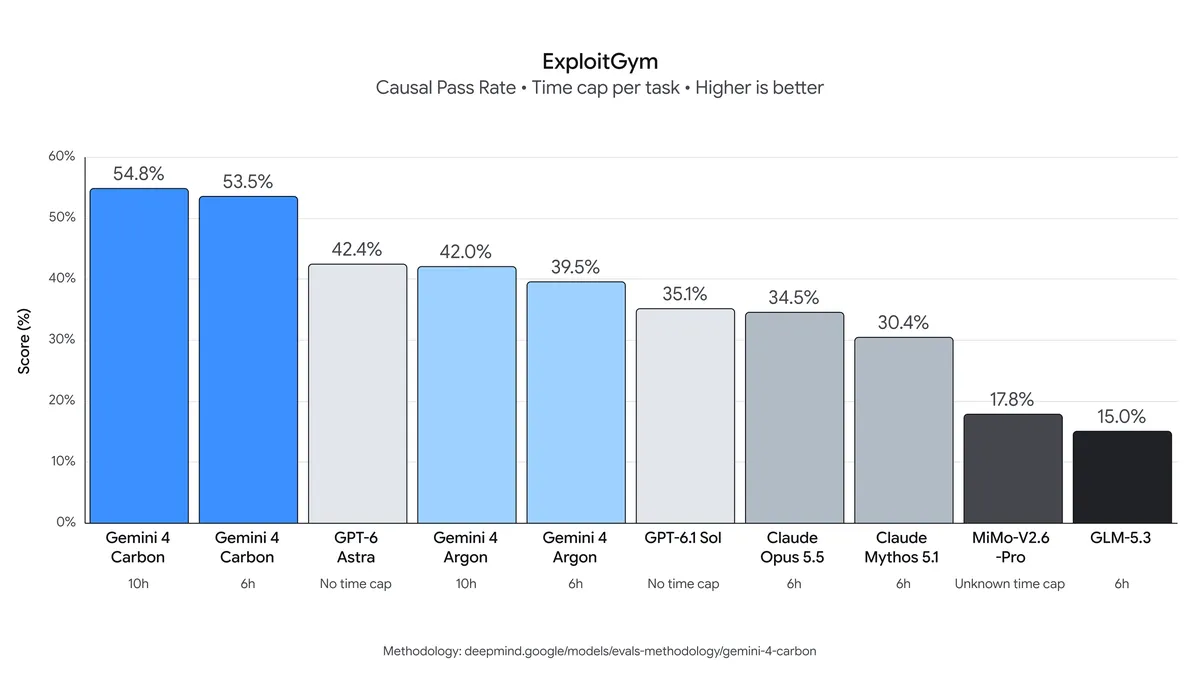
ExploitGym
54.8%
#1 of 10 models with a reported result
-
ExploitGym
54.8%
10h
#1 of 10 models with a reported result
-
ExploitGym
53.5%
6h
-
FrontierSWE v2
61.2%
#3 of 5 models with a reported result
-
GraphWalks
96.2%
256k to 1M, BFS (F1)
#1 of 2 models with a reported result
Show all 20
-
OSWorld 2.1
81.5%
Offline subset
#2 of 9 models with a reported result
-
RiemannBench
80.0%
#1 of 2 models with a reported result
-
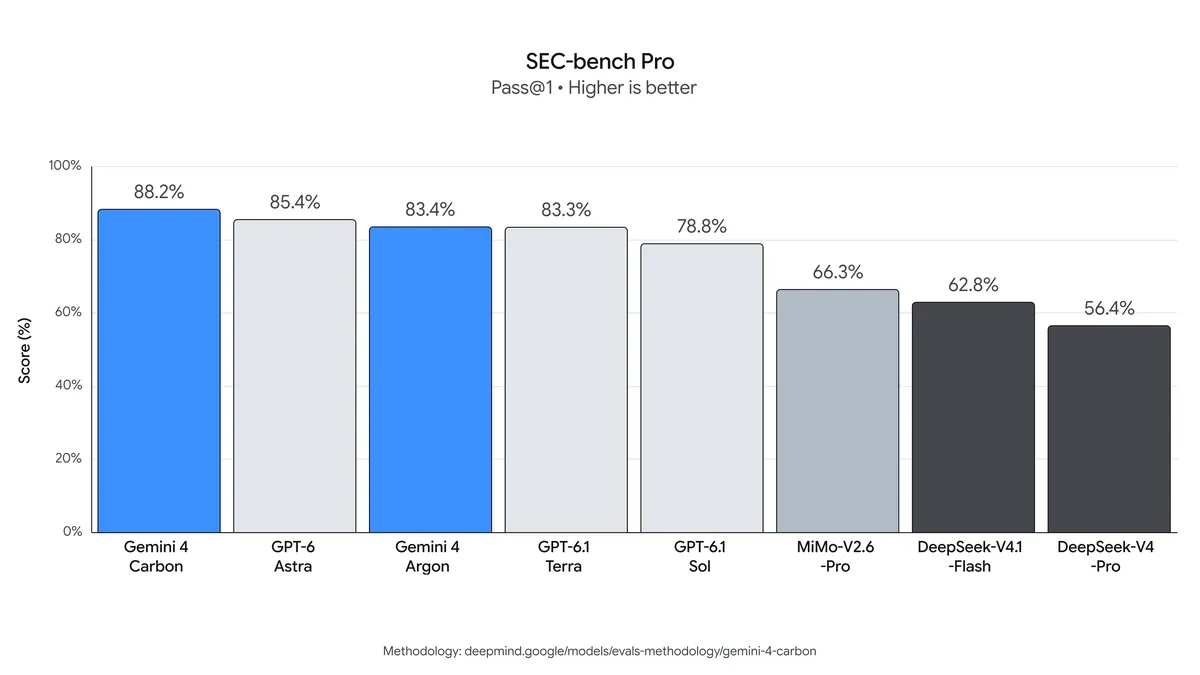
SEC-Bench Pro
88.2%
#1 of 10 models with a reported result
-
SEC-Bench Pro
88.2%
Pass@1
#1 of 10 models with a reported result
-
SWE-sweep
9.6%
#1 of 2 models with a reported result
-
Terminal-Bench 4.0-AA
65.2%
#1 of 3 models with a reported result
-
Terminal-Bench-Science 0.1 (AA)
64.8%
#1 of 2 models with a reported result
-
Vals Index v2.2
70.4%
#1 of 3 models with a reported result
Independent results so far
73 scores from 73 boards that test models themselves. Ranks compare Gemini 4 Carbon with every model on the same board.
General (16)
| Benchmark | Score | Rank | Setting | Source |
|---|---|---|---|---|
| LiveBench data analysis | 86.5% | #1 of 31 | — | LiveBench |
| LMArena Text | 1538 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: English | 1530 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: entertainment and media | 1527 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: instruction following | 1539 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: longer queries | 1549 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: multi-turn | 1569 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: non-English | 1534 | #1 of 151 | High | LMArena (Hugging Face dataset) |
Show all 16
| LMArena Text: Russian | 1560 | #1 of 151 | High | LMArena (Hugging Face dataset) |
|---|---|---|---|---|
| LMArena Text: writing and language | 1542 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: Chinese | 1613 | #2 of 146 | High | LMArena (Hugging Face dataset) |
| LMArena Text: creative writing | 1533 | #2 of 151 | High | LMArena (Hugging Face dataset) |
| Vals Index | 70.5% | #3 of 34 | — | Vals Index |
| Furniture assembly | 77.5% | #6 of 36 | High | Epoch AI benchmarking hub |
| GDPval-AA | 1733 | #8 of 117 | High | Artificial Analysis |
| Long context reasoning (AA-LCR) | 79.3% | #54 of 176 | High | Artificial Analysis |
Coding (13)
| Benchmark | Score | Rank | Setting | Source |
|---|---|---|---|---|
| CursorBench 4.0 | 60.4% | #1 of 20 | high | CursorBench (Cursor) |
| LiveBench coding | 91.0% | #1 of 31 | — | LiveBench |
| LMArena Text: coding | 1564 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: software and IT | 1552 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| Terminal-Bench 4.0 (Artificial Analysis run) | 65.2% | #2 of 111 | High | Artificial Analysis |
| LMArena WebDev: HTML | 1770 | #3 of 104 | High | LMArena (Hugging Face dataset) |
| LMArena WebDev | 1768 | #4 of 105 | High | LMArena WebDev |
| LMArena WebDev: React | 1792 | #4 of 97 | High | LMArena (Hugging Face dataset) |
Show all 13
| FrontierSWE | 61.2% | #5 of 22 | High | Epoch AI benchmarking hub |
|---|---|---|---|---|
| Terminal-Bench 4 (Vals AI) | 63.1% | #5 of 57 | Mini-SWE-agent | Vals AI boards |
| ALE-Bench | 2374.7 | #6 of 110 | High | ALE-Bench (Sakana AI) |
| FrontierCode 2.0 | 40.6% | #7 of 55 | High | Artificial Analysis |
| Vibe Code Bench (Vals AI) | 89.1% | #9 of 105 | OpenHands | Vals AI boards |
Reasoning (13)
| Benchmark | Score | Rank | Setting | Source |
|---|---|---|---|---|
| ARC-AGI | 98.5% | #1 of 75 | Medium | Epoch AI benchmarking hub |
| GPQA Diamond (Epoch AI run) | 96.5% | #1 of 115 | High | Epoch AI benchmarking hub |
| LMArena Text: expert | 1582 | #1 of 150 | High | LMArena (Hugging Face dataset) |
| LMArena Text: hard prompts | 1551 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: hard prompts in English | 1545 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| ARC-AGI-2 | 94.2% | #2 of 76 | Medium | Epoch AI benchmarking hub |
| Chess puzzles | 78.0% | #2 of 81 | High | Epoch AI benchmarking hub |
| EBR-bench | 87.6% | #2 of 29 | High | Epoch AI benchmarking hub |
Show all 13
| HLE-Diamond (Artificial Analysis run) | 69.1% | #2 of 74 | High | Artificial Analysis |
|---|---|---|---|---|
| SimpleBench | 92.6% | #2 of 72 | — | Epoch AI benchmarking hub |
| CritPt v2, hard subset (Artificial Analysis run) | 69.0% | #4 of 56 | High | Artificial Analysis |
| Mystery game puzzles | 73.0% | #5 of 75 | High | Epoch AI benchmarking hub |
| LiveBench reasoning | 90.6% | #10 of 31 | — | LiveBench |
Agentic work (10)
| Benchmark | Score | Rank | Setting | Source |
|---|---|---|---|---|
| APEX-Agents | 84.2% | #1 of 59 | — | Epoch AI benchmarking hub |
| Legal Research Bench (Vals AI) | 55.8% | #1 of 83 | — | Vals AI boards |
| Vending-Bench 2 | $16,484 | #1 of 62 | — | Epoch AI benchmarking hub |
| LiveBench research | 92.5% | #2 of 31 | — | LiveBench |
| Tax Agent Bench (Vals AI) | 51.8% | #2 of 77 | — | Vals AI boards |
| Design Arena: agents building mobile apps | 1284 | #4 of 55 | — | Design Arena |
| LiveBench long agentic | 72.7% | #5 of 31 | — | LiveBench |
| Harvey's Legal Agent Benchmark (Vals AI) | 17.5% | #7 of 34 | — | Vals AI boards |
Show all 10
| LiveBench browser | 80.0% | #10 of 31 | — | LiveBench |
|---|---|---|---|---|
| Design Arena: spreadsheets | 1224 | #15 of 39 | — | Design Arena |
Knowledge (8)
| Benchmark | Score | Rank | Setting | Source |
|---|---|---|---|---|
| FACTS Benchmark Suite | 78.4% | #1 of 23 | — | Kaggle Benchmarks |
| LMArena Text: business and finance | 1520 | #1 of 151 | High | LMArena (Hugging Face dataset) |
| LMArena Text: legal and government | 1542 | #1 of 150 | High | LMArena (Hugging Face dataset) |
| AA-Omniscience | 53.5 | #2 of 58 | High | Artificial Analysis |
| LMArena Text: science | 1535 | #2 of 151 | High | LMArena (Hugging Face dataset) |
| SimpleQA Verified | 77.7% | #2 of 77 | High | Epoch AI benchmarking hub |
| LMArena Text: medicine and healthcare | 1525 | #4 of 150 | High | LMArena (Hugging Face dataset) |
| PRBench Legal | 53.3% | #4 of 39 | — | Scale SEAL leaderboards |
Web design (6)
| Benchmark | Score | Rank | Setting | Source |
|---|---|---|---|---|
| Design Arena: 3D | 1434 | #5 of 121 | — | Design Arena |
| LiveBench design | 80.2% | #5 of 31 | — | LiveBench |
| Design Arena: UI components | 1357 | #7 of 124 | — | Design Arena |
| Design Arena: all code categories | 1348 | #9 of 129 | — | Design Arena |
| Design Arena: websites | 1319 | #9 of 134 | — | Design Arena |
| Design Arena: game dev | 1326 | #16 of 128 | — | Design Arena |
Math (5)
| Benchmark | Score | Rank | Setting | Source |
|---|---|---|---|---|
| MathArena | 85.4% | #1 of 72 | high | MathArena |
| OTIS Mock AIME | 100.0% | #1 of 115 | High | Epoch AI benchmarking hub |
| FrontierMath, tier 4 | 95.1% | #4 of 66 | High | Epoch AI benchmarking hub |
| LMArena Text: mathematical work | 1538 | #4 of 147 | High | LMArena (Hugging Face dataset) |
| FrontierMath, tiers 1 to 3 | 90.5% | #6 of 80 | High | Epoch AI benchmarking hub |
Intelligence (2)
| Benchmark | Score | Rank | Setting | Source |
|---|---|---|---|---|
| AA Intelligence Index | 60.0 | #2 of 55 | — | Artificial Analysis (via OpenRouter) |
| Epoch Capabilities Index | 169.8 | #2 of 125 | — | Epoch AI benchmarking hub |