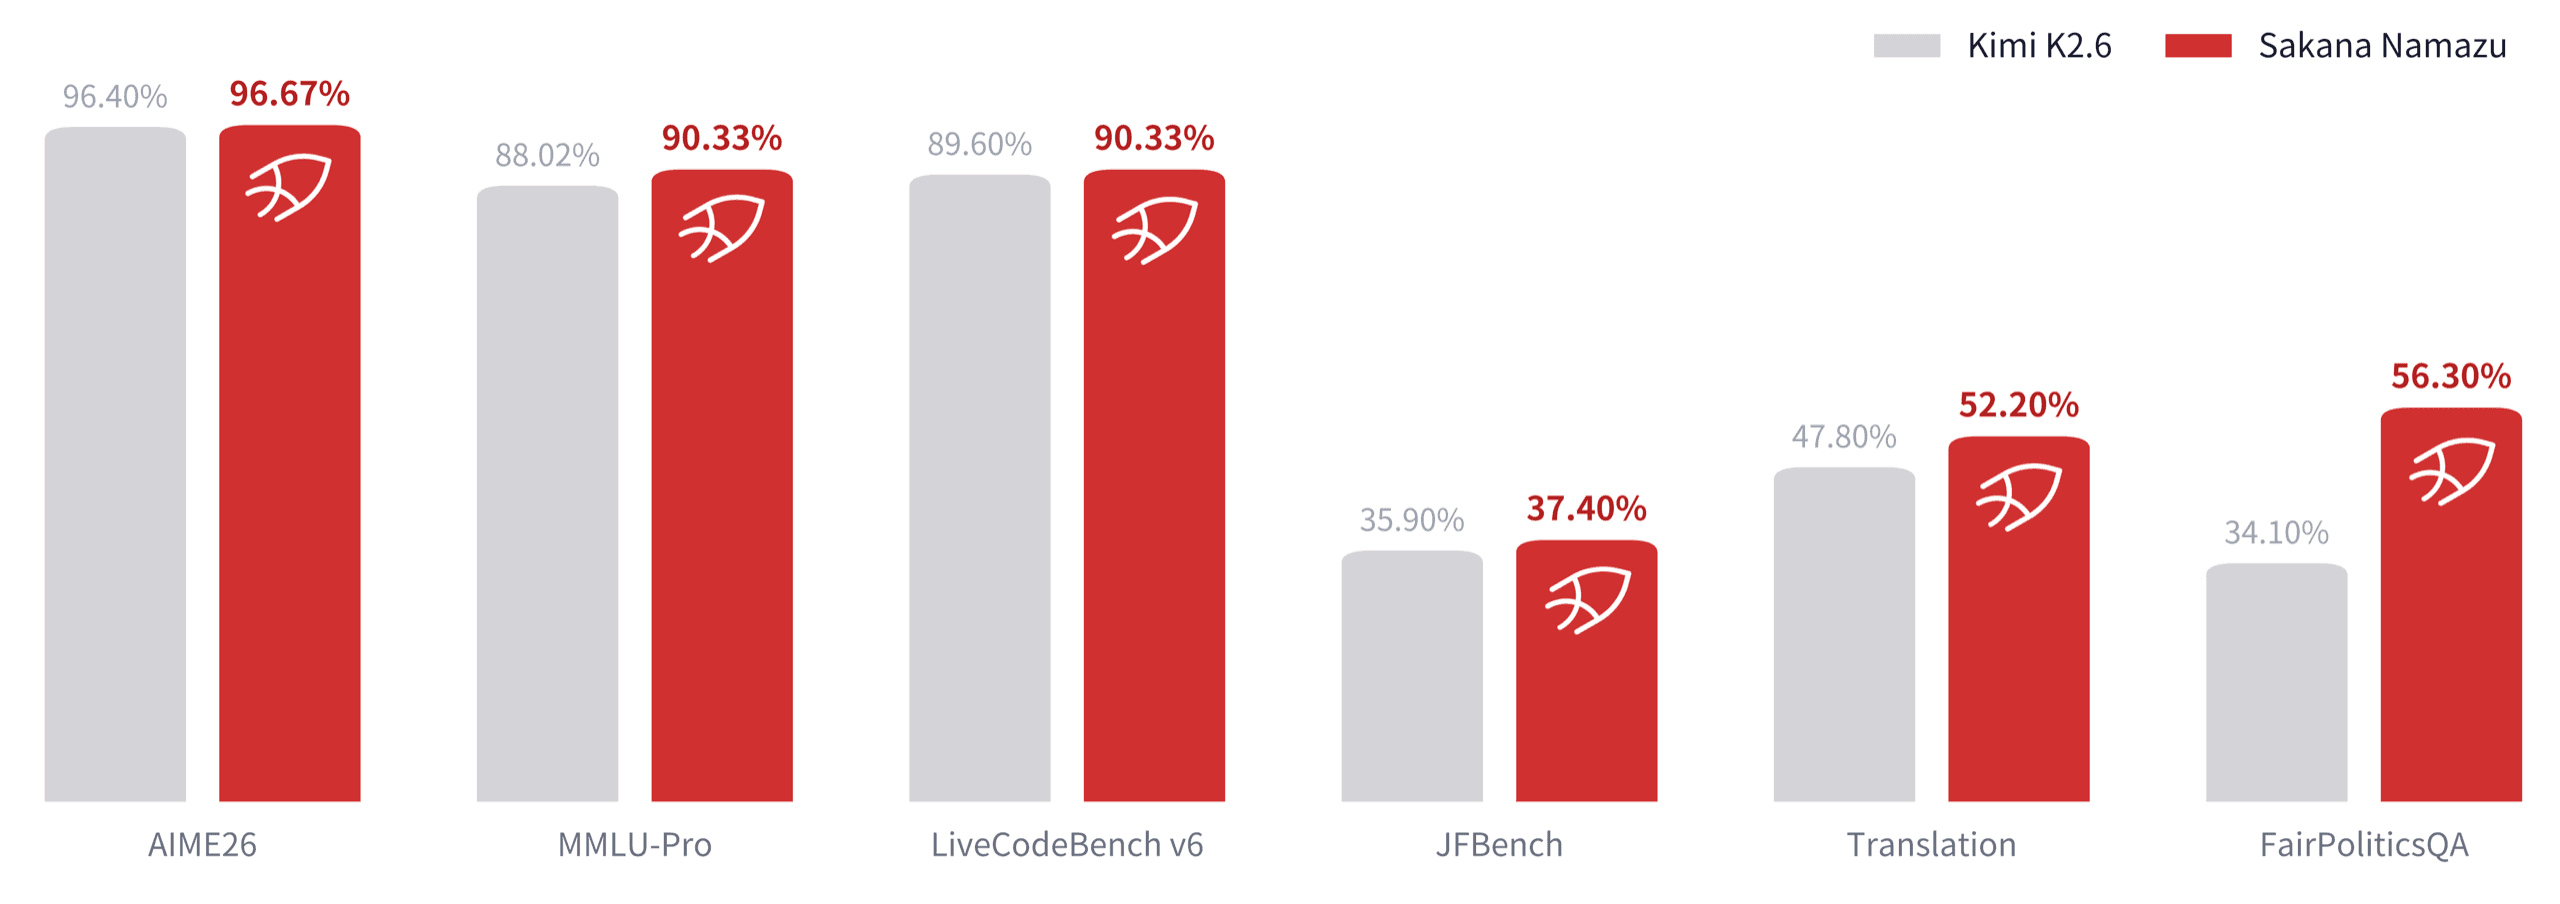
Benchmarks / LiveCodeBench v6 LiveCodeBench v6 leaderboard As of November 14, 2026, among the results listed here, Qwen3.8 Flash has the highest reported LiveCodeBench v6 score, 91.9, published by Qwen, ahead of Sakana Namazu at 90.3. 14 models have a LiveCodeBench v6 result in our records.
Scores as the model makers published them, not re-run by us; each row links to its announcement.
Share Cite Cite this page: LLMBenchmark.ai, "LiveCodeBench v6 Leaderboard: Scores Reported by AI Labs (November 2026)", https://llmbenchmark.ai/benchmarks/livecodebench-v6, accessed November 14, 2026 .
Copy citation Best reported score
91.9
Qwen3.8 Flash
Reported by Qwen, August 26, 2026
14 models ranked · 6 makers
Reported LiveCodeBench v6 scores LiveCodeBench v6 scores reported by model makers Rank Model Score Setting Reported by Date 1 Qwen3.8 Flash 91.9 Not published Qwen August 26, 2026 (model release) 2 Sakana Namazu 90.3 Not published Sakana August 11, 2026 (model release) · read from the maker's chart 3 Qwen3.8 27B 90.3 Not published Qwen August 14, 2026 (model release) 4 Kimi K2.6 89.6 Not published Moonshot AI April 20, 2026 (model release) 5 Kimi K2.5 85 Not published Moonshot AI April 20, 2026 (model release) 6 GLM 4.7 84.9 Not published Z.ai December 22, 2025 (model release) 7 Qwen3.6 27B 83.9 Not published Qwen August 14, 2026 (model release) 8 Kimi K2 Thinking 83.1 Not published Moonshot AI November 6, 2025 (model release) 9 GLM 4.6V 82.8 Not published Z.ai December 22, 2025 (model release) 10 LFM3-1.7B 73.5 Not published Liquid November 6, 2026 (model release) 11 Granite 4.2 8B 73.2 Not published IBM Granite August 31, 2026 (model release) 12 LFM2.5-2.6B Retired 60.6 Not published Liquid November 6, 2026 (model release) 13 Kimi K2 0905 56.1 Not published Moonshot AI November 6, 2025 (model release) 14 Kimi-K2-Base 26.3 Base model evaluation results; Pass@1 Moonshot AI July 11, 2025 (model release)
Other reported runs How much to trust these numbers
Source Reported by the model makers themselves. Not re-run by LLMBenchmark or anyone independent.
Settings Settings differ between makers. Check the Setting column before comparing two scores.
Spread 91.9 to 26.3 across 14 models.
Freshness Newest result published November 6, 2026; oldest July 11, 2025.
Charts Some values were read from charts in the announcements. Two independent readings had to match exactly. What LiveCodeBench v6 measures Models generate code and reason through competitive programming tasks; the supplied results do not explain what the score means.