Healthbench Professional leaderboard
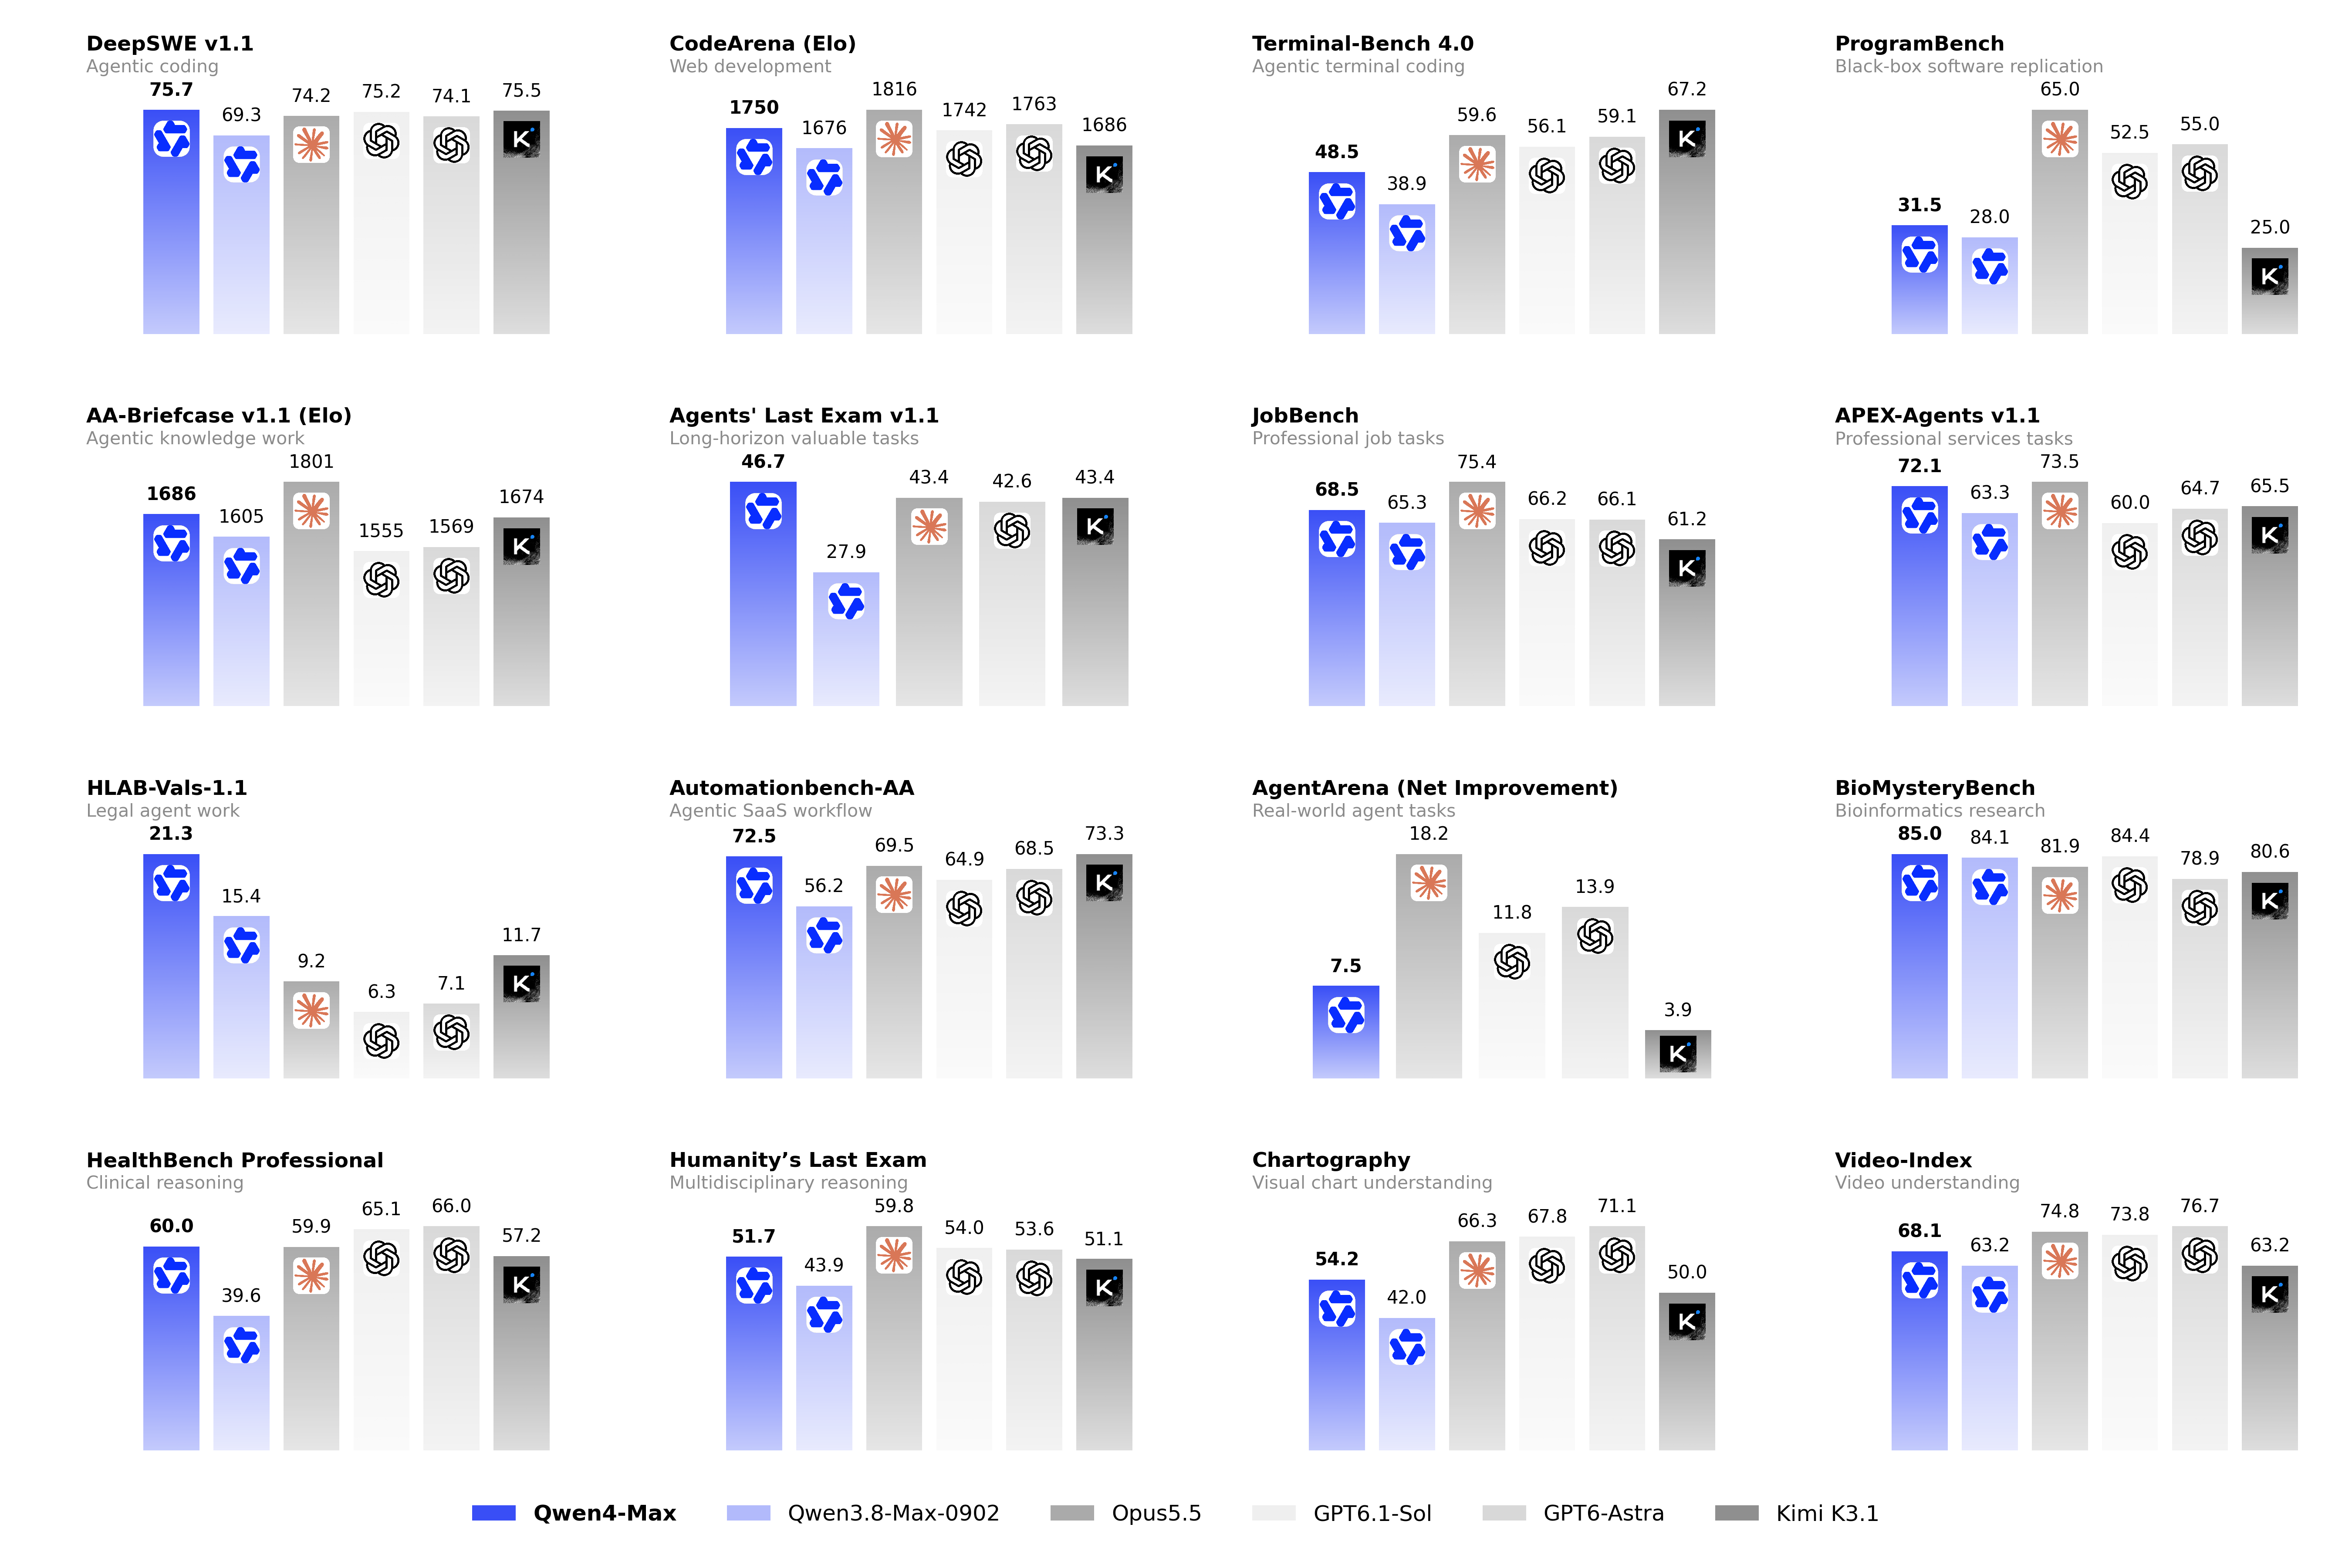
As of November 22, 2026, among the results listed here, inclusionAI Ling 3.1 Flash has the highest reported Healthbench Professional score, 65.4, published by inclusionAI, ahead of Qwen4 Max at 60. 6 models have a Healthbench Professional result in our records.
Scores as the model makers published them, not re-run by us; each row links to its announcement.
6 models ranked · 3 makers
| Rank | Model | Score | Setting | Reported by | Date |
|---|---|---|---|---|---|
| 1 | Ling 3.1 Flash | 65.4 | Not published | inclusionAI | October 2, 2026 (model release) · read from the maker's chart |
| 2 | Qwen4 Max | 60 | Not published | Qwen | August 3, 2026 · read from the maker's chart |
| 3 | GPT-5.6 Terra | 57.7 | Not published | OpenAI | August 7, 2025 (model release) |
| 4 | GPT-5.6 Luna | 55.7 | Not published | OpenAI | August 7, 2025 (model release) |
| 5 | GPT-5.5 | 49.5 | Not published | OpenAI | August 7, 2025 (model release) |
| 6 | Qwen3.8 Max (0902) | 39.6 | Not published | Qwen | August 3, 2026 · read from the maker's chart |

How much to trust these numbers
- Source
- Reported by the model makers themselves. Not re-run by LLMBenchmark or anyone independent.
- Settings
- All ranked results use the same reported setting.
- Spread
- 65.4 to 39.6 across 6 models.
- Freshness
- Newest result published October 2, 2026; oldest August 7, 2025.
- Charts
- Some values were read from charts in the announcements. Two independent readings had to match exactly.
What Healthbench Professional measures
Models handle real clinician tasks in conversations, and their rubric-based scores reflect performance and safety on those tasks. Source: HealthBench Professional: Evaluating Large Language Models on Real Clinician Chats