Enter opens the highlighted result. Esc closes.

DeepSWE v1.1 leaderboard

As of November 22, 2026, among the results listed here, Meta Muse Wonder has the highest reported DeepSWE v1.1 score, 78.8 (max), published by Meta, ahead of Google Gemini 4 Argon at 77.9. 32 models have a DeepSWE v1.1 result in our records.

Scores as the model makers published them, not re-run by us; each row links to its announcement.

Best reported score

78.8

Meta Muse Wonder

Reported by Meta, October 12, 2026 · max

Runner-up

77.9

Google Gemini 4 Argon

Reported by Google, October 13, 2026

32 models ranked · 15 makers

Reported DeepSWE v1.1 scores

DeepSWE v1.1 scores reported by model makers
Rank Model Score Setting Reported by Date
1 Muse Wonder 78.8 max Meta October 12, 2026 (model release)
2 Gemini 4 Argon 77.9 Not published Google October 13, 2026 (model release)
3 DeepSeek V4.1 Flash 1017 77 Not published DeepSeek October 17, 2026 (model release)
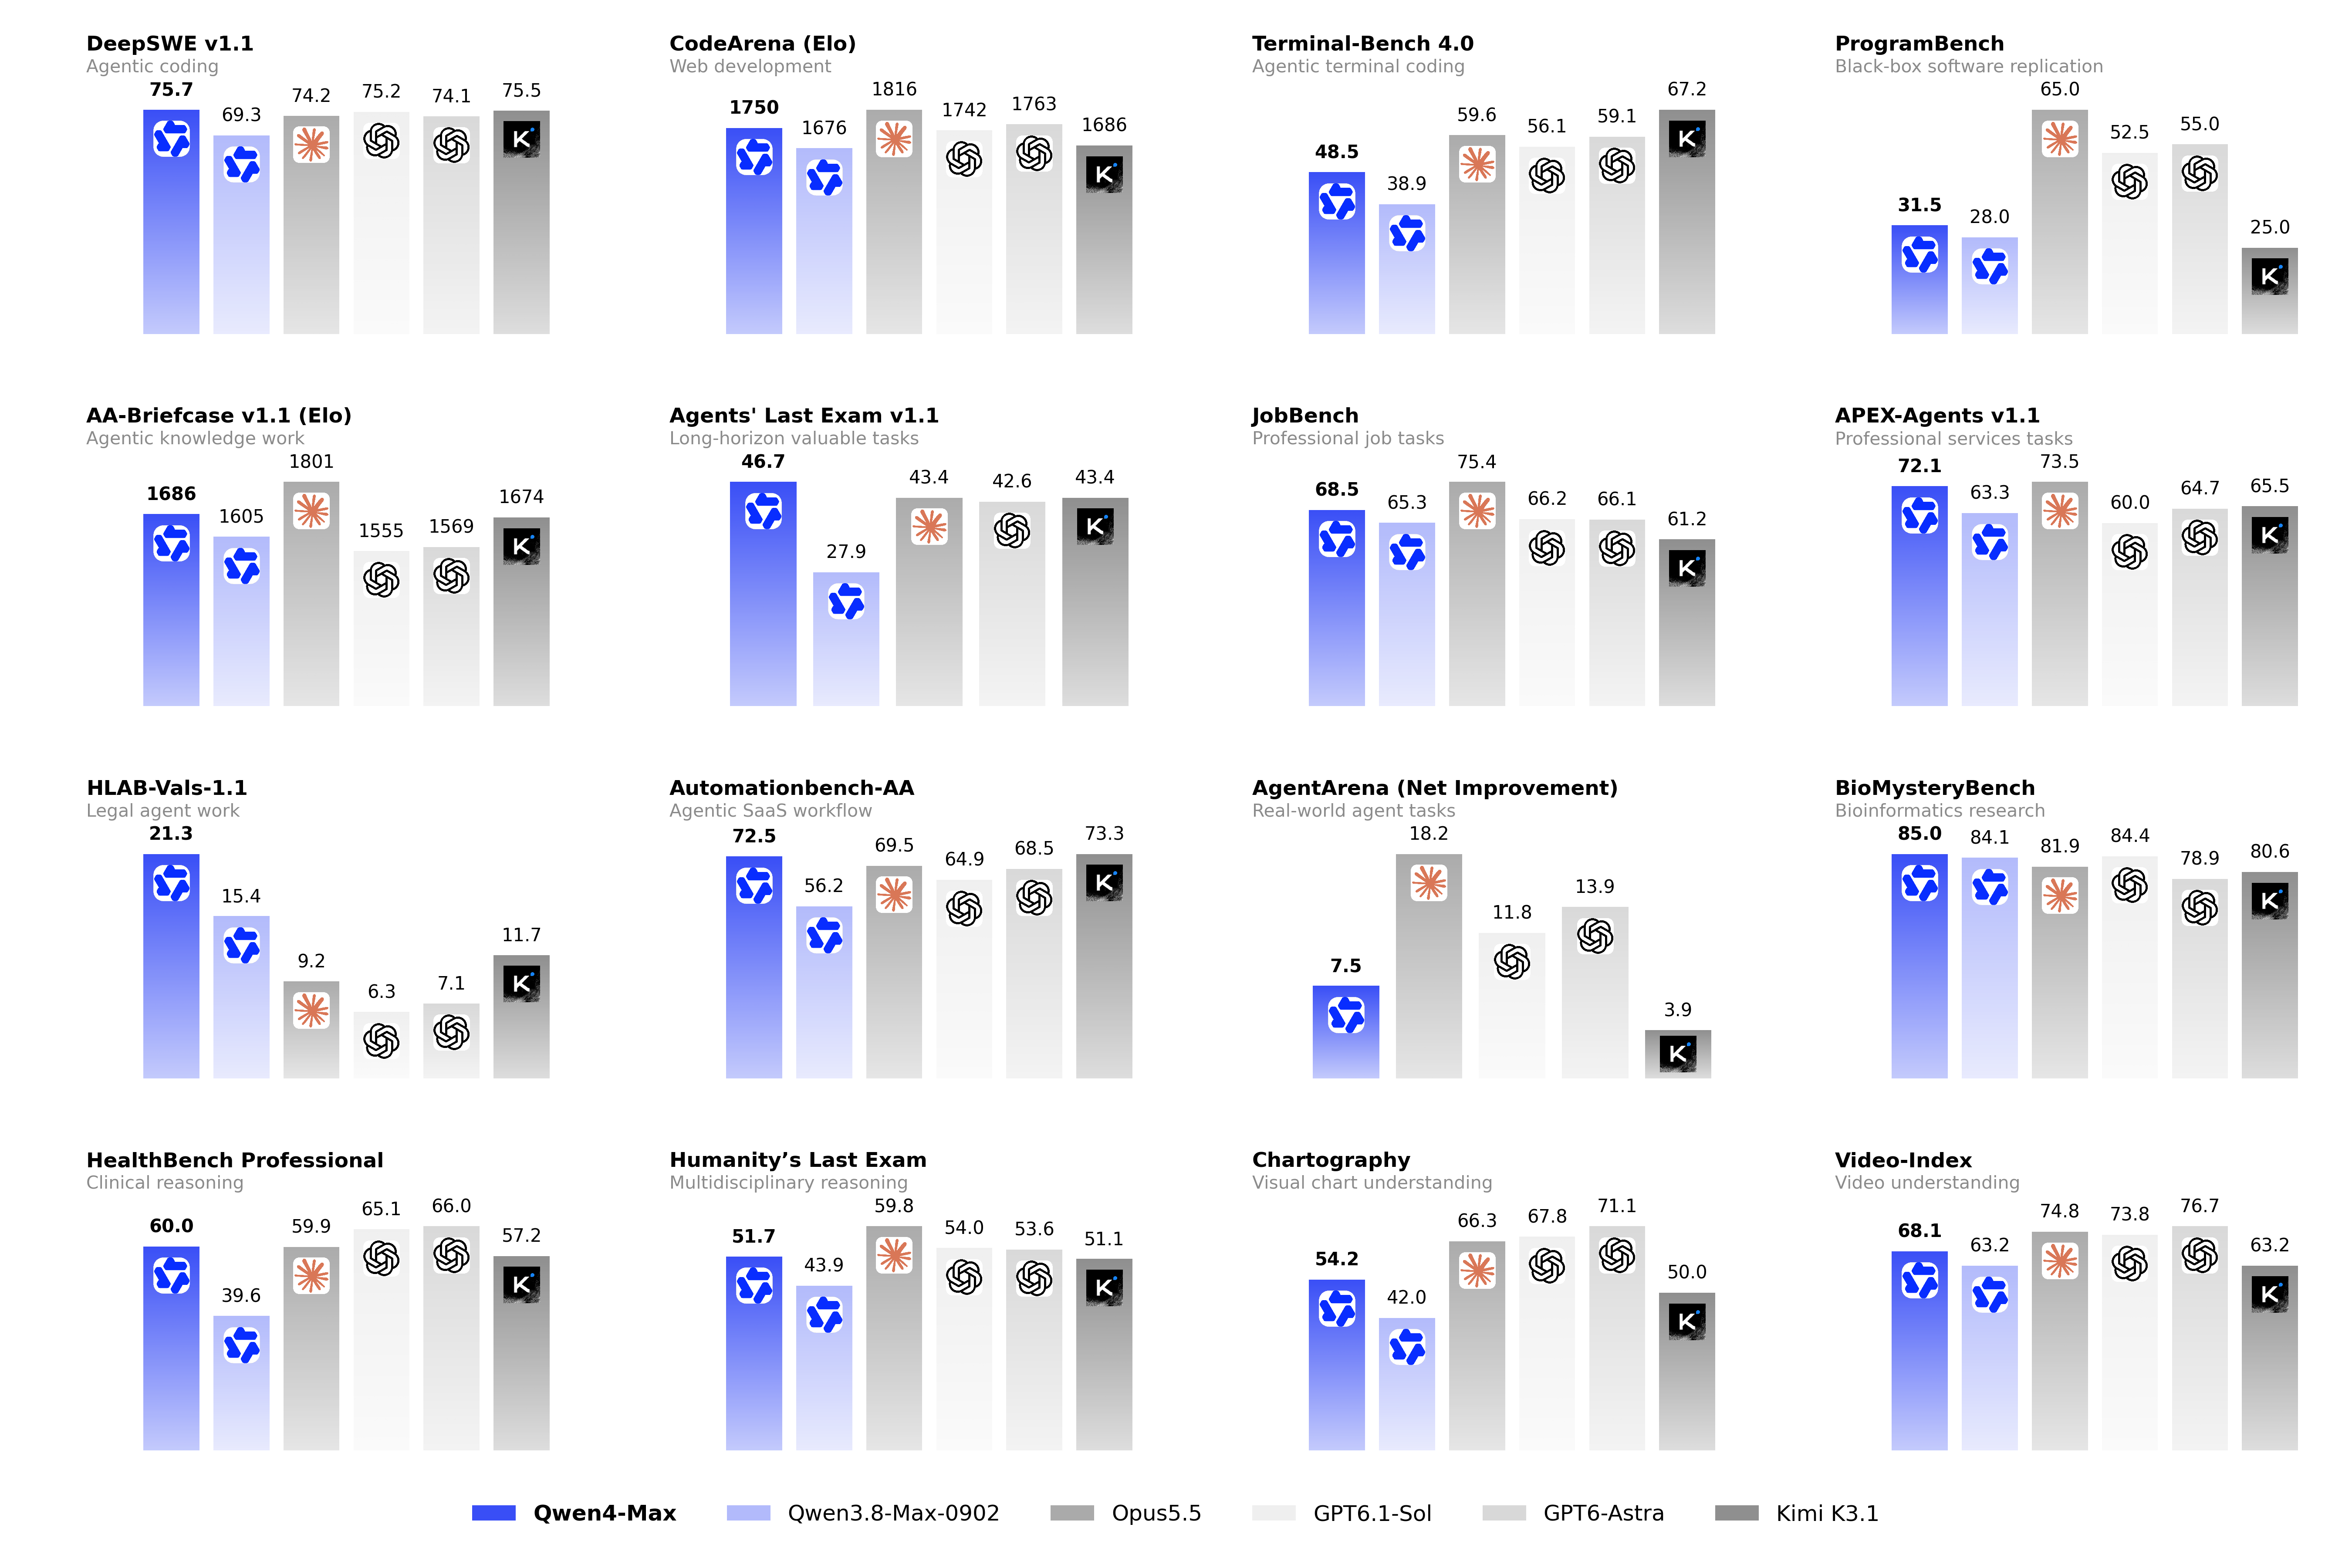
4 Qwen4 Max 75.7 Not published Qwen August 3, 2026 · read from the maker's chart
5 Muse Spark 1.3 75.4 max Meta August 5, 2026 (model release)
6 Ember-1 75.2 Not published Fireworks September 23, 2026
7 DeepSeek V4.1 Flash 74.2 Not published DeepSeek October 17, 2026 (model release)
8 MiniMax M3.1 Flash 73.7 Not published MiniMax October 19, 2026 (model release)
9 MiMo-V2.6-Pro 71.9 Not published Xiaomi September 21, 2026 (model release)
10 U Pareto 26.10 69.9 Not published Unbiased October 13, 2026 (model release)
11 Qwen3.8 Max (0902) 69.3 Not published Qwen August 3, 2026 · read from the maker's chart
12 GPT-6 Sol 68.8 max effort OpenAI September 22, 2026 (model release)
13 MiMo-V2.6-Flash 67.9 Not published Xiaomi September 21, 2026 (model release)
14 Step 5 Preview 67.7 High StepFun October 8, 2026 (model release)
15 GPT-5.6 Luna 67.2 Not published OpenAI August 7, 2025 (model release)
16 Grok 4.6 65.2 High xAI September 21, 2026
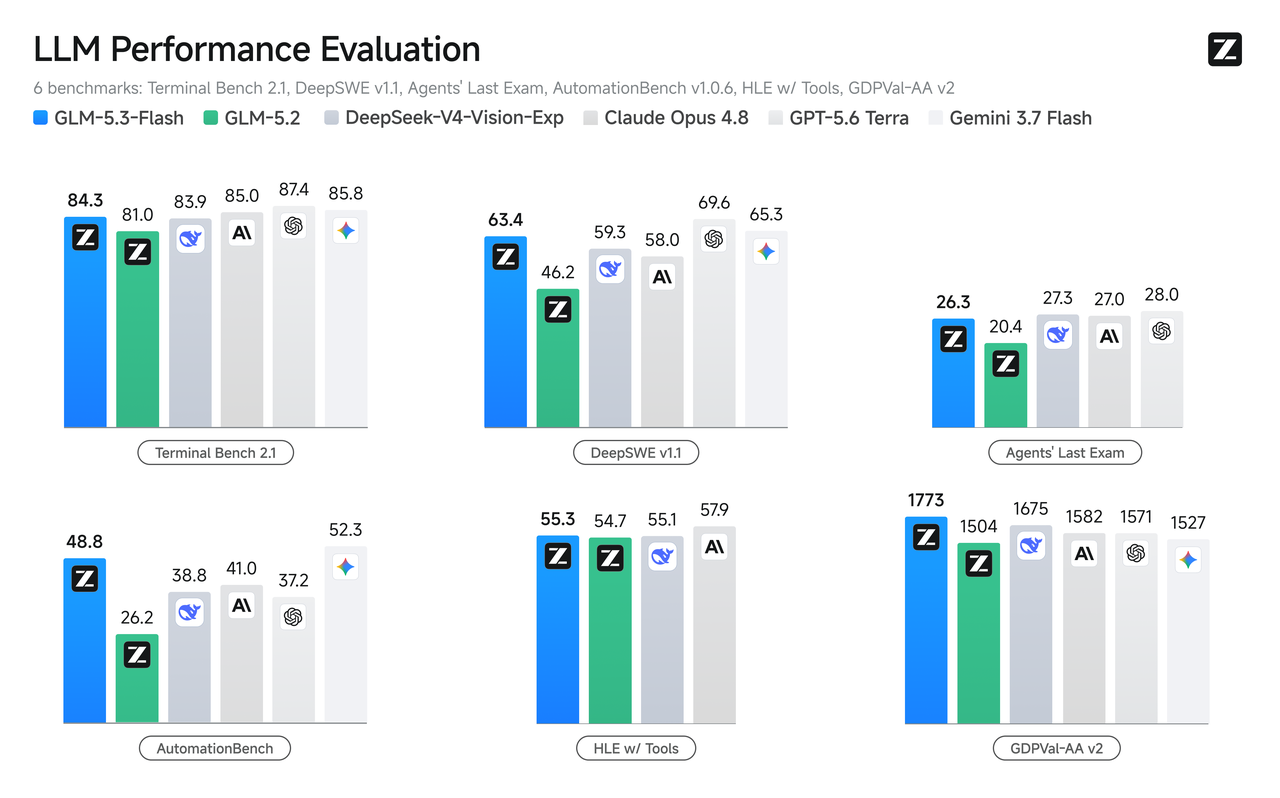
17 GLM 5.3 Flash 63.4 Not published Z.ai August 26, 2026 (model release) · read from the maker's chart
18 Muse Spark 1.2 59.3 Muse Code Meta August 21, 2026 (model release) · read from the maker's chart
19 Qwen3.8 Flash 58.7 Not published Qwen August 26, 2026 (model release)
20 N Nex-N2.5-Pro 55.8 Not published Nex AGI September 8, 2026 (model release)
21 Muse Spark 1.1 53 mini-swe-agent Meta August 21, 2026 (model release) · read from the maker's chart
21 Grok 4.5 53 mini-swe-agent harness run by Datacurve xAI July 16, 2026
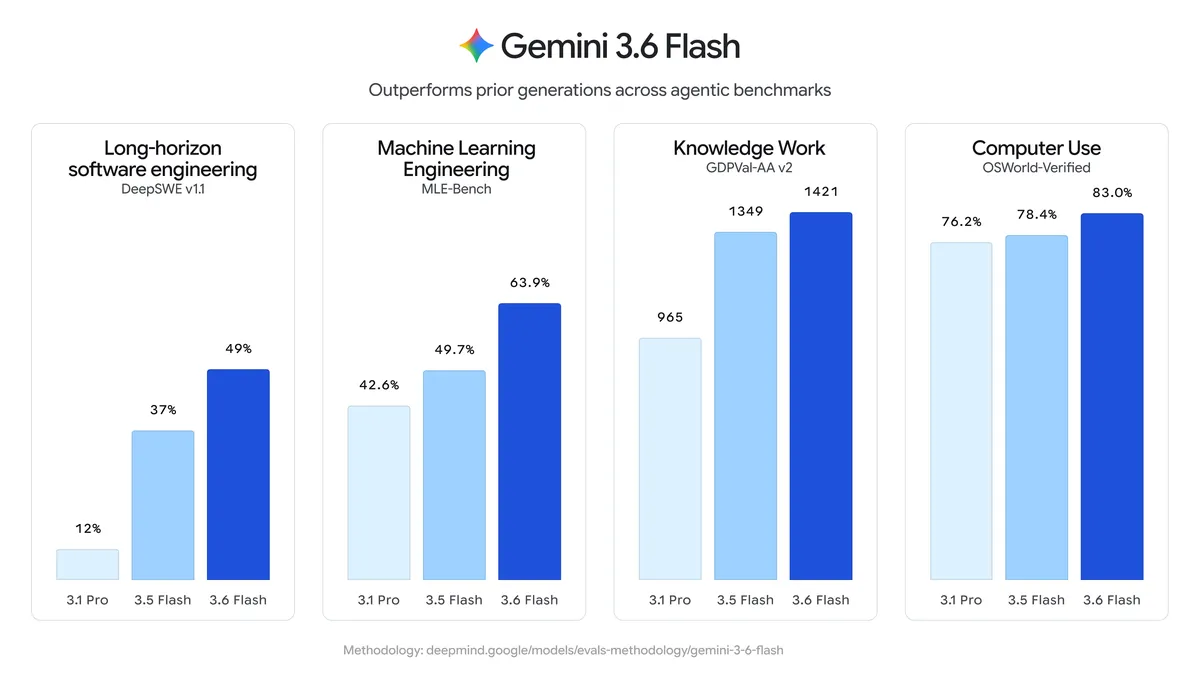
23 Gemini 3.6 Flash 49 Not published Google July 21, 2026 · read from the maker's chart
24 R DaisyRose 27B 46.2 Not published Radixark November 21, 2026 (model release)
25 R Beam 1.0 501B A23B 43.3 BF16 Reflection October 16, 2026 (model release)
26 Qwen3.8 27B 42.2 Not published Qwen August 14, 2026 (model release)
27 Gemini 3.5 Flash 37 Not published Google July 21, 2026 · read from the maker's chart
28 N Nex-N2.5-Mini 36.1 Not published Nex AGI September 8, 2026 (model release)
29 Qwen3.7 Max 21.6 Not published Qwen August 3, 2026
30 MiMo-V2.5-Pro 19 Not published Xiaomi September 21, 2026 (model release)
31 Qwen3.7 Plus 16.5 Not published Qwen August 26, 2026 (model release)
32 Qwen3.6 27B 13.3 Not published Qwen August 14, 2026 (model release)

Other reported runs

DeepSWE v1.1 scores reported by model makers, other reported runs
Model Score Setting Reported by Date
DeepSeek V4.1 Flash 74.2 Resolved DeepSeek September 10, 2026 (model release)
Muse Spark 1.2 55 xhigh Meta August 5, 2026 (model release)
Qwen3.7 Plus 14.2 Not published Qwen August 14, 2026 (model release)
Qwen3.8 Max (0902) 56.6 Not published Qwen August 3, 2026
R Beam 1.0 501B A23B 43 FP8 Reflection October 16, 2026 (model release)
R Beam 1.0 501B A23B 42.7 NVFP4 Reflection October 16, 2026 (model release)

How much to trust these numbers

Source
Reported by the model makers themselves. Not re-run by LLMBenchmark or anyone independent.
Settings
Settings differ between makers. Check the Setting column before comparing two scores.
Spread
78.8 to 13.3 across 32 models.
Freshness
Newest result published November 21, 2026; oldest August 7, 2025.
Charts
Some values were read from charts in the announcements. Two independent readings had to match exactly.

What DeepSWE v1.1 measures

DeepSWE v1.1 asks models to complete real software engineering tasks; its score is the percentage of tasks passed on the first attempt. Source: datacurve/deep-swe · Datasets at Hugging Face